
In an era defined by an unprecedented deluge of digital content, the simple act of locating a highly specific piece of information can often feel like searching for a needle in a haystack. Queries such as “what episode does Marissa die in The OC” are emblematic of a common user need: to pinpoint a precise moment, detail, or event within an expansive media library. While seemingly trivial, the technological underpinnings that allow for the efficient resolution of such queries are anything but. They represent the cutting edge of information retrieval, natural language processing, and database management, crucial for enhancing user experience across streaming platforms, educational resources, and entertainment archives.
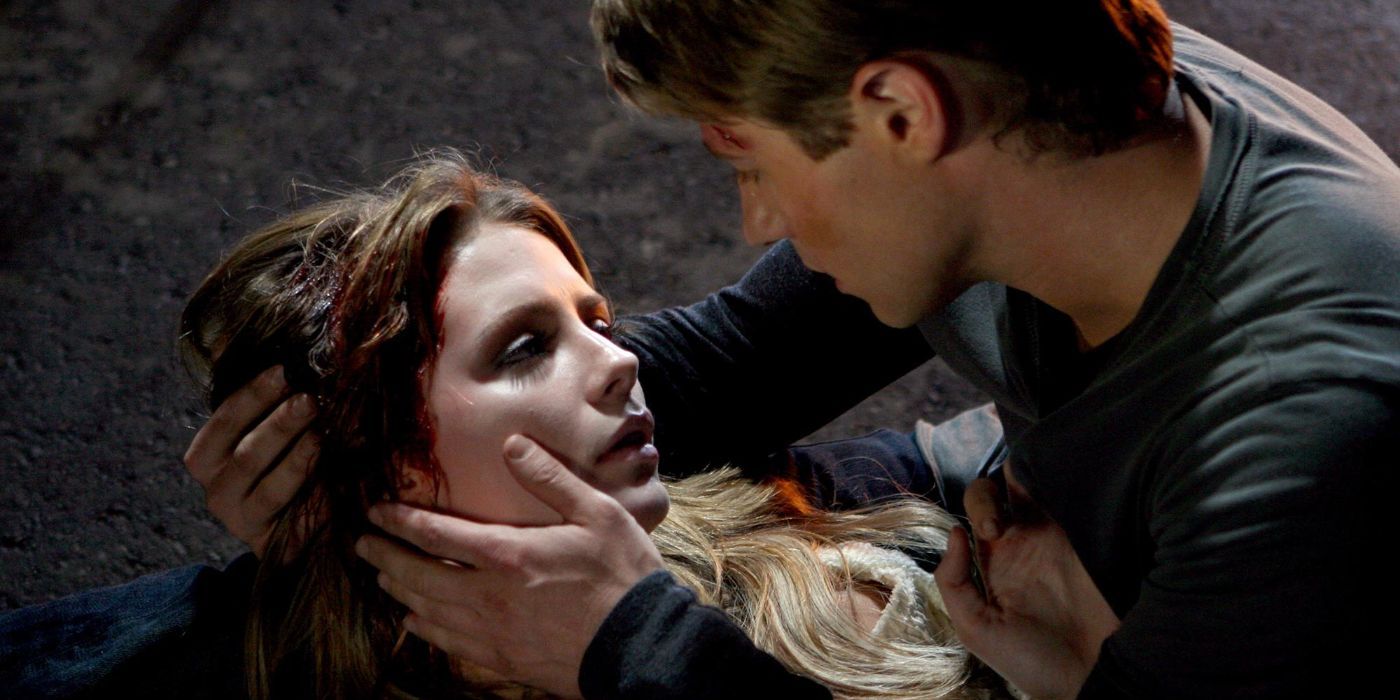
This article delves into the technological innovations that enable users to navigate the complexities of digital media, transforming vague inquiries into actionable answers. We will explore how advancements in AI, search algorithms, metadata management, and community-driven data enrichment are redefining our interaction with vast content repositories, making the once-elusive detail instantly accessible.
The Quest for Specifics: Information Retrieval in the Streaming Era
The explosion of streaming services has democratized access to an unimaginable volume of film, television, documentaries, and user-generated content. With this abundance comes the inherent challenge of discoverability. Beyond browsing genres or trending titles, users frequently arrive with highly specific questions, often related to plot points, character arcs, or obscure details. The ability of a system to answer “what episode does Marissa die in The OC” is not just about returning a search result; it’s about understanding the intent behind the query and connecting it to the correct segment of a vast, unstructured dataset.
From Keyword Searches to Contextual Understanding
Early digital search capabilities were largely predicated on keyword matching. A query would scan titles, descriptions, and basic metadata for exact or partial word matches. While effective for broad searches, this approach quickly falters when users seek information that is not explicitly tagged with simple keywords. The question of Marissa’s death in “The OC,” for instance, might not be explicitly mentioned in an episode title or summary. It requires a deeper, contextual understanding of the narrative content. Modern search engines and content management systems (CMS) now employ sophisticated algorithms that move beyond mere keywords, attempting to interpret the semantic meaning of a query. This involves analyzing the relationships between words, identifying named entities (like “Marissa” and “The OC”), and inferring the underlying user intent.
The Challenge of Niche Queries in Vast Catalogs
The sheer scale of today’s media catalogs presents a formidable challenge. A typical streaming service can host tens of thousands of hours of content, each comprising hundreds or thousands of individual scenes. Manually tagging every detail within this content is impractical, if not impossible. This necessitates the development of automated or semi-automated systems that can ingest, process, and index media content in a way that makes niche queries resolvable. The accuracy and speed with which these systems can retrieve information directly impact user satisfaction and engagement. Overcoming this challenge requires innovative approaches to data structuring, content analysis, and the continuous refinement of search heuristics.
AI and Machine Learning: Revolutionizing Media Discovery
Artificial Intelligence (AI) and Machine Learning (ML) are at the forefront of transforming how we interact with digital media. These technologies are crucial for bridging the gap between a user’s natural language query and the specific information buried within hours of audiovisual content. By enabling systems to “understand” and “learn” from data, AI/ML empowers more intelligent and responsive information retrieval.
Natural Language Processing (NLP) for Deeper Insights
Natural Language Processing (NLP) is the branch of AI that enables computers to understand, interpret, and generate human language. For queries like “what episode does Marissa die in The OC,” NLP plays a pivotal role. It allows the system to:
-
Parse the query: Breaking down the sentence structure to identify the subject (“Marissa”), the action (“die”), and the context (“The OC”).
-
Entity Recognition: Identifying “Marissa” and “The OC” as specific entities, linking them to known characters and media titles within the database.
-
Sentiment Analysis (indirectly relevant): While not directly applicable to factual retrieval, NLP can also infer the emotional tone of a query, which can be useful for recommending related content or adjusting search parameters in other contexts.
-
Semantic Search: Moving beyond literal keyword matching to understand the meaning of the query. An NLP-powered system can infer that “Marissa’s death” is a significant plot point and search for episodes containing events related to major character departures or fatal incidents.
Advanced NLP models, often based on deep learning architectures like transformers, are capable of processing vast amounts of textual metadata (scripts, subtitles, summaries) and even analyzing spoken dialogue within the media itself to extract relevant information.
Predictive Analytics and Personalized Recommendations
Beyond direct query resolution, AI/ML also enhances the overall media discovery experience through predictive analytics. While not directly answering “what episode does Marissa die in The OC,” these systems can:
-
Anticipate User Needs: By analyzing a user’s viewing history, search patterns, and interactions, AI can predict future queries or interests. If a user frequently searches for character-specific plot points, the system might pre-index or highlight such information for related shows.
-
Personalized Information Delivery: AI can tailor the presentation of information. For instance, after answering the Marissa query, the system might suggest related episodes focusing on other character deaths, or a retrospective on the show’s most dramatic moments, based on the user’s viewing habits. This moves beyond simple retrieval to a more proactive and personalized information service.
Streaming Platforms as Intelligent Databases
Modern streaming platforms are far more than just content delivery networks; they are sophisticated, intelligent databases designed for optimal content storage, retrieval, and user interaction. The ability to answer specific queries is deeply embedded in their architectural design and operational strategies.
Enhanced Search Features and Metadata Tagging
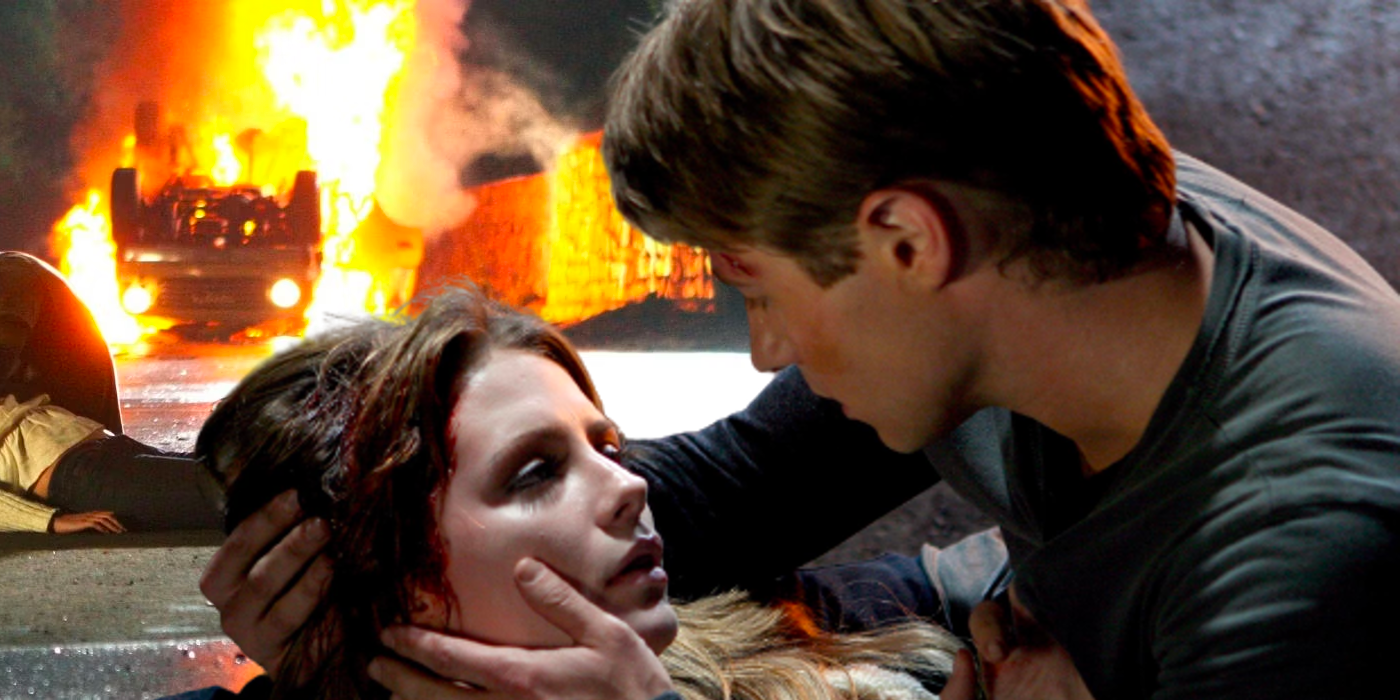
The foundation of any successful information retrieval system lies in its metadata. Streaming platforms invest heavily in robust metadata strategies that go far beyond basic title, genre, and cast information. For content like “The OC,” this can include:
-
Detailed Plot Summaries: Summaries that highlight key events, character developments, and major turning points.
-
Scene-Level Tagging: Increasingly, platforms are using AI and human curation to tag specific scenes with keywords, character names, emotions, and plot events. This allows for granular searches, enabling a system to pinpoint the exact scene where Marissa dies, not just the episode.
-
Dialogue Indexing: Subtitle and closed caption data are often indexed, making every word spoken within a show searchable. This allows users to find specific quotes or conversations, and by extension, events associated with those dialogues.
-
Character Profiles and Arcs: Dedicated metadata for individual characters, including their major story beats, relationships, and ultimate fates, provides a rich dataset for targeted queries.
These detailed metadata schemas, combined with powerful search APIs, allow platforms to respond to complex, nuanced queries with high accuracy.
Interactive Overlays and Fan-Driven Content Integration
Some advanced streaming platforms and companion apps are experimenting with interactive overlays and direct integration of external information sources. Imagine watching an episode of “The OC” and being able to pause, click on a character, and instantly see their bio, key plot points, or even fan-contributed trivia.
-
X-Ray Feature (Amazon Prime Video): A prime example of this, X-Ray allows viewers to access real-time information about actors, music, and trivia during playback. While currently focused on general information, the underlying technology could easily extend to specific plot event details, such as “Marissa’s death scene occurs at 34:12 in this episode.”
-
Fan Wiki Integration: Future iterations could see direct integration with trusted fan wikis or community databases, leveraging crowdsourced information that is often more detailed and rapidly updated than official platform metadata. This blurs the line between official content delivery and external, community-generated knowledge bases.
The Role of Community and Crowdsourcing in Data Enrichment
While AI and platform infrastructure are critical, the human element—specifically, fan communities—plays an indispensable role in enriching the data landscape, especially for niche queries. Enthusiastic fans often generate, curate, and verify information at a level of detail that even professional content managers struggle to match.
Fan Wikis and Collaborative Databases
Websites like Fandom (formerly Wikia) host countless fan-created wikis for nearly every popular media franchise. These platforms are living, breathing databases meticulously maintained by dedicated fans. For a show like “The OC,” a fan wiki would undoubtedly have a detailed page for Marissa Cooper, outlining her entire character arc, including the specific episode and circumstances of her death.
-
Granular Detail: Fan wikis often contain minute details not found in official summaries, such as specific timestamps for key events, character connections, and behind-the-scenes trivia.
-
Rapid Updates: Information is often updated in real-time as new episodes air or new details emerge, making them highly current sources of information.
-
Cross-Referencing: These wikis are expertly cross-referenced, allowing users to navigate from a character to an episode, to a specific plot point, and back again, creating a dense web of interconnected information.
Technologies that can intelligently parse and integrate data from these collaborative sources into primary search results or platform features could significantly enhance information retrieval for highly specific queries.
Social Media as a Real-time Information Hub
Social media platforms, while often chaotic, also serve as powerful real-time information hubs. When a major plot point occurs, like a character’s death, discussions erupt instantly. Hashtags, trending topics, and dedicated fan groups quickly aggregate information. While not a structured database, the collective intelligence of social media can quickly confirm or reveal details that might take longer to appear in official metadata or even wikis. Search algorithms increasingly factor in social media trends and discussions to inform real-time search results, particularly for breaking or rapidly evolving content.
The Future of Media Information Access: Seamless and Instantaneous
The trajectory of technology points towards an increasingly seamless and instantaneous experience for media information access. The goal is to make answering “what episode does Marissa die in The OC” not just possible, but effortlessly integrated into the user’s interaction with media.
Voice Assistants and Conversational AI
The proliferation of voice assistants like Siri, Alexa, and Google Assistant is transforming how we query digital systems. Conversational AI allows users to ask questions in natural language, without needing to type keywords. “Hey Google, what episode does Marissa die in The OC?” is a perfectly natural and increasingly effective way to get an answer.
-
Contextual Dialogue: Future advancements will enable these assistants to maintain context across multiple turns of a conversation, allowing for follow-up questions like, “And who was she with?” or “What season was that?”
-
Multi-Modal Responses: Answers won’t just be verbal; they could involve displaying the episode directly on a smart TV, playing a clip, or showing a summary on a smart display.
Hyper-Personalization and Anticipatory Search
The ultimate frontier is hyper-personalization, where systems not only answer specific questions but also anticipate them. Imagine a streaming platform that, based on your viewing habits and engagement with “The OC,” might proactively notify you, “You’re approaching the episode where Marissa Cooper dies. Would you like to view a summary, or skip to that episode?” This level of anticipatory search and information delivery leverages deep user profiling and advanced predictive analytics.
In conclusion, the ability to effortlessly answer a seemingly simple query like “what episode does Marissa die in The OC” is a testament to the sophisticated interplay of advanced technologies. From intelligent search algorithms and robust metadata management to the transformative power of AI, NLP, and the collaborative efforts of fan communities, technology continues to reshape our access to information. As these systems evolve, the digital labyrinth of media content will become ever more navigable, offering users precise, contextual, and increasingly personalized pathways to the specific details they seek.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.