
The seemingly simple query, “What type of animal is a snail?” belies a profound technological challenge and triumph that underpins much of our modern digital experience. While on the surface it’s a question of biology, in the realm of artificial intelligence and information technology, it represents a quintessential example of data classification, knowledge retrieval, and semantic understanding. This query, and millions like it, are the proving grounds for sophisticated AI systems designed to categorize, contextualize, and deliver precise information from the vast, unstructured ocean of digital data.
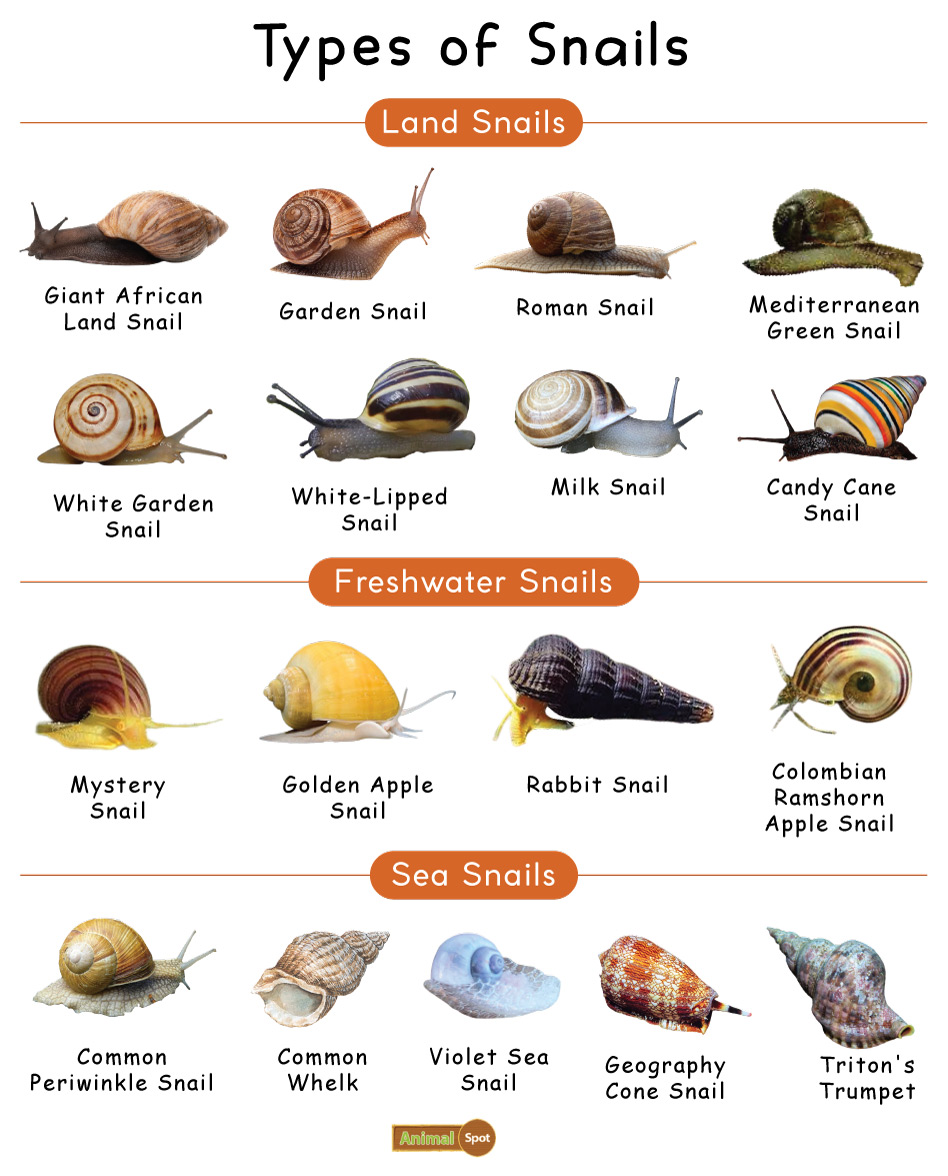
Understanding what type of animal a snail is—a mollusc, a gastropod, an invertebrate—requires more than just keyword matching; it demands an understanding of hierarchical relationships, attributes, and biological classifications. This fundamental need for structured knowledge is precisely where AI, particularly through advancements in natural language processing (NLP), machine learning, and knowledge graphs, has become indispensable. This article delves into how AI addresses such queries, transforming raw data into actionable intelligence across various domains, starting from the humble snail and expanding into complex organizational challenges.
AI’s Foundational Role in Biological Taxonomy and Beyond
At its core, the question about a snail is one of classification. For centuries, humans have meticulously categorized the natural world, building complex taxonomies. Today, AI systems are not merely mimicking this process but augmenting it, making information accessible, searchable, and interconnected on an unprecedented scale.
From Simple Queries to Complex Ontologies
When a user asks “What type of animal is a snail?”, an advanced AI system doesn’t just look for pages containing the words “snail” and “animal.” Instead, it interprets the intent: “classify ‘snail’ within a biological hierarchy.” The AI then taps into its knowledge base, which has been trained on encyclopedic amounts of biological data, to identify ‘snail’ as an entity. It understands that ‘snail’ is an instance of a ‘gastropod,’ which is a type of ‘mollusc,’ which in turn is an ‘invertebrate animal.’ This intricate web of relationships is an ontology – a formal representation of knowledge as a set of concepts within a domain and the relationships between those concepts.
The progression from a simple textual query to a multi-layered, semantically rich answer illustrates AI’s ability to move beyond superficial keyword analysis. It highlights the transformation of information into structured knowledge, where relationships between entities are explicitly defined and understood, enabling far more nuanced and accurate responses than traditional search methods.
The Evolution of Knowledge Representation
Early attempts at AI-driven knowledge systems, often called “expert systems,” relied on hand-coded rules and explicit logical relationships. While effective for narrow domains, they were brittle and difficult to scale. The advent of machine learning, particularly deep learning, revolutionized this. Modern AI knowledge representation is dynamic, leveraging vast datasets to learn patterns, infer relationships, and build comprehensive knowledge graphs autonomously or semi-autonomously. These systems can process new information, identify new entities or relationships, and continuously refine their understanding of the world, much like a biologist who constantly updates their understanding of species classifications with new discoveries. This iterative learning process ensures that the AI’s “understanding” of a snail, or any other entity, remains current and comprehensive.
The Mechanics of AI-Driven Knowledge Bases and Data Classification
The capacity of AI to answer questions about snails or any other entity is not magic; it’s the result of sophisticated engineering combining several powerful technological components. These components work in concert to parse human language, categorize data, and build interconnected knowledge structures.
Natural Language Processing (NLP) and Semantic Search
The first hurdle for any AI system dealing with human queries is understanding language. Natural Language Processing (NLP) is the branch of AI that enables computers to interpret, understand, and generate human language. When “What type of animal is a snail?” is input, NLP techniques come into play:
-
Tokenization and Parsing: The query is broken down into individual words (tokens), and its grammatical structure is analyzed.
-
Named Entity Recognition (NER): “Snail” is identified as a specific entity.
-
Intent Recognition: The phrase “what type of animal is” is understood as a request for classification or categorization within the biological domain.
-
Semantic Understanding: This is where NLP truly shines. It doesn’t just match words; it grasps the meaning and relationships between them. It understands that “snail” belongs to a broader concept of “animal” and seeks a more specific categorization.
This semantic understanding powers “semantic search,” which goes beyond keyword matching to interpret the context and meaning of a query, delivering more relevant and comprehensive results.
Machine Learning in Data Labeling and Categorization
At the heart of any robust AI classification system are machine learning algorithms. These algorithms are trained on enormous datasets, learning to recognize patterns and make predictions or classifications.
-
Supervised Learning: For classification tasks, models are trained on labeled data (e.g., thousands of examples where “snail” is labeled as “mollusc,” “gastropod,” etc.). Deep neural networks, with their ability to process complex patterns, are particularly effective here, learning intricate features from text descriptions, images, or even genomic data to accurately classify biological entities.
-
Unsupervised Learning: In cases where labels are scarce, unsupervised learning algorithms can discover hidden patterns and groupings within data. This might involve clustering similar entities based on shared attributes, aiding in the initial structuring of a knowledge base.
-
Feature Engineering: AI models learn to extract relevant “features” from the data. For text, this could be word embeddings that capture semantic relationships (e.g., “snail” and “slug” might have similar embeddings). For images, it could be visual characteristics that distinguish a snail from an insect.
This continuous training and refinement allow AI systems to classify new, unseen data with high accuracy, constantly enriching their understanding of the world.
Knowledge Graphs: The Backbone of Intelligent Classification
While NLP and machine learning provide the analytical power, knowledge graphs provide the structural integrity for intelligent classification. A knowledge graph is a highly interconnected network of entities (like “snail,” “mollusc,” “habitat,” “diet”) and the relationships between them (e.g., “Snail ISA Mollusc,” “Snail LIVESIN Terrestrial Environments,” “Snail EATS Plants”).
This graph-based structure is incredibly powerful because it allows AI to:

-
Infer Relationships: If a snail is a mollusc, and all molluscs are invertebrates, the AI can infer that a snail is an invertebrate, even if that specific relationship wasn’t explicitly coded.
-
Provide Contextual Answers: Instead of just saying “a snail is a mollusc,” the AI can provide additional context by traversing the graph: “A snail is a gastropod mollusc, an invertebrate animal characterized by a coiled shell and a muscular foot, typically living in terrestrial or aquatic environments.”
-
Enhance Discoverability: By connecting diverse pieces of information, knowledge graphs enable users to explore related concepts, enriching their understanding beyond the initial query.
These knowledge graphs are central to the operations of major search engines and intelligent assistants, providing the framework for their ability to deliver precise, contextual, and comprehensive answers to a vast array of questions, from the simple to the complex.
Broader Applications of AI Classification Across Industries
The principles and technologies that allow AI to classify a snail are not confined to zoology. They are universally applicable, driving efficiency, innovation, and deeper insights across virtually every industry.
Scientific Research and Data Synthesis
In scientific fields from biology and medicine to materials science, researchers are overwhelmed by an exponential growth in data. AI classification systems are invaluable for:
-
Accelerating Drug Discovery: Classifying molecular structures, genetic sequences, and patient data to identify potential drug targets or disease biomarkers.
-
Automated Literature Review: Categorizing and summarizing vast amounts of research papers, helping scientists stay abreast of new findings and identify gaps in knowledge.
-
Environmental Monitoring: Classifying species, environmental conditions, and ecological patterns from sensor data or satellite imagery to inform conservation efforts.
By automating the tedious task of data organization and synthesis, AI allows scientists to focus on higher-level analysis and discovery.
Business Intelligence and Market Analysis
For businesses, AI classification transforms raw operational data into strategic intelligence. Similar principles used to classify animals are applied to:
-
Customer Segmentation: Classifying customers based on demographics, behavior, and preferences to tailor marketing campaigns and product offerings.
-
Product Categorization: Organizing vast product catalogs for e-commerce platforms, optimizing search and recommendation engines.
Market Trend Analysis: Identifying emerging trends by classifying news articles, social media discussions, and financial reports, giving businesses a competitive edge.
-
Document Management: Automatically classifying legal documents, invoices, and contracts, streamlining operations and improving compliance.
Digital Content Management and Personalization
In the digital content landscape, AI classification is crucial for managing the deluge of information and delivering personalized experiences.
-
Content Recommendation: Streaming services and news platforms classify content (movies, articles, music) based on genres, themes, and user preferences to provide tailored recommendations.
-
Search Engine Optimization (SEO): AI-powered classifiers help search engines understand the topic and intent of web pages, improving search result relevance.
-
Moderation and Filtering: Classifying user-generated content for appropriateness, identifying spam, or flagging harmful material, ensuring safer digital environments.
Challenges and Future Directions in AI Classification
While AI has made incredible strides, the journey is far from over. Significant challenges remain, and future developments promise even more sophisticated and nuanced classification capabilities.
Ambiguity, Context, and Continuous Learning
The real world is messy, and ambiguity is common. A “snail” might be a biological entity, a derogatory term for a slow person, or a brand name. AI systems must become better at discerning context and handling polysemy (words with multiple meanings). This requires more sophisticated reasoning capabilities, common-sense knowledge, and the ability to learn continuously from new data and user feedback without extensive human intervention. The goal is “lifelong learning” for AI systems, enabling them to adapt to evolving terminologies and new discoveries without requiring complete retraining.
Ethical Considerations and Data Bias
The power of AI classification comes with significant ethical responsibilities. If the training data is biased – reflecting human prejudices or skewed representations – the AI will perpetuate and amplify those biases in its classifications. This can lead to unfair or discriminatory outcomes, particularly in sensitive applications like loan approvals, hiring, or criminal justice. Ensuring fairness, transparency, and accountability in AI classification systems is paramount. This involves meticulous data curation, explainable AI (XAI) techniques to understand how classifications are made, and robust auditing processes.
The Synergy of Human and Artificial Intelligence
Despite the impressive capabilities of AI, human intelligence remains indispensable, especially for complex or nuanced classifications. Humans provide the initial training data, define the overarching ontologies, and offer critical oversight. In the future, “human-in-the-loop” systems will become even more prevalent, where AI handles the bulk of classification, but human experts review ambiguous cases, validate new categories, and provide feedback for continuous improvement. This symbiotic relationship, where AI augments human cognitive abilities, promises the most robust and trustworthy classification systems.
Conclusion
The seemingly straightforward question, “What type of animal is a snail?”, opens a window into the complex, dynamic world of artificial intelligence and its transformative power. It highlights how AI, through NLP, machine learning, and knowledge graphs, can take a simple query, understand its semantic intent, and deliver precise, contextual, and comprehensive answers. From classifying biological species to segmenting customers, optimizing supply chains, and curating digital content, the ability of AI to categorize and organize information is a cornerstone of modern technological advancement. As AI continues to evolve, addressing challenges like ambiguity and bias, we can anticipate even more intelligent, adaptive, and ethically sound classification systems that will further enhance our ability to navigate and understand the vast ocean of human knowledge. The future of information is not just about having data; it’s about AI’s capacity to flawlessly tell us what type of ‘animal’ each piece of it truly is.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.