
In the rapidly evolving landscape of technology, from software engineering to artificial intelligence, the concept of an “experiment” has moved out of the chemistry lab and into the integrated development environment (IDE). Whether a developer is fine-tuning a recommendation algorithm or a UI/UX designer is testing the placement of a call-to-action button, the integrity of the results depends entirely on an understanding of variables. In a technical context, variables are the specific elements, conditions, or characteristics that are manipulated, measured, or controlled to understand the cause-and-effect relationships within a system.
For tech professionals, mastering variables is not just an academic exercise; it is the foundation of the scientific method applied to product growth. Without a rigorous approach to identifying and isolating variables, software updates become guesswork, and AI models become “black boxes” that yield unpredictable results. To build robust, scalable, and user-centric technology, one must first master the mechanics of experimental variables.
The Core Foundation: Defining Variables in Tech-Centric Experiments
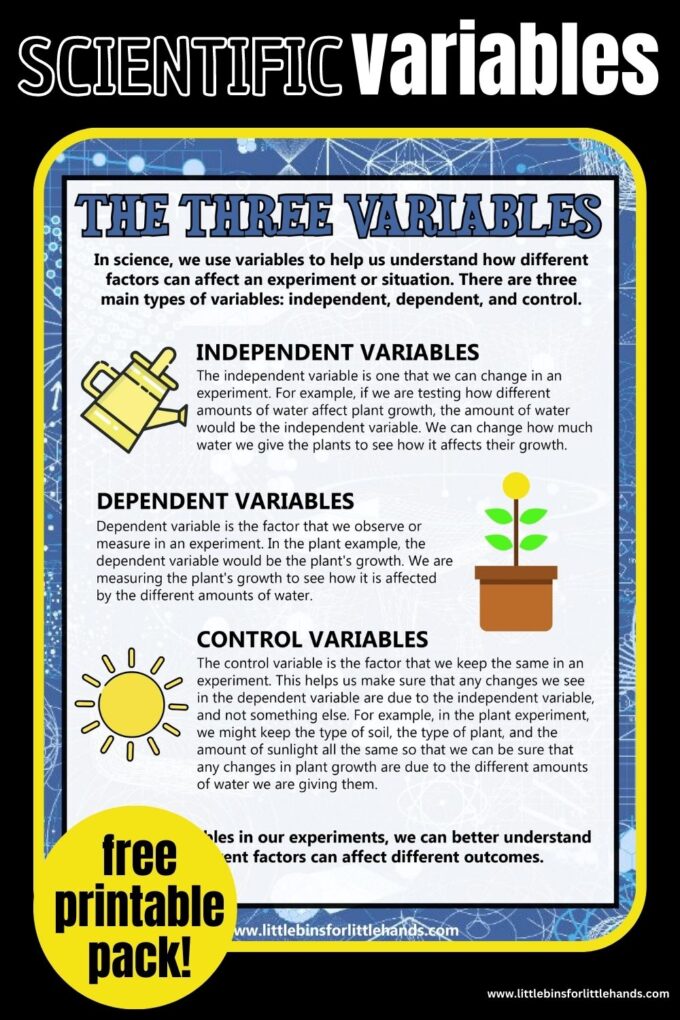
In any technological experiment, variables are categorized based on the role they play in the test. In the tech sector, these are usually divided into independent, dependent, and control variables. Each plays a distinct role in ensuring that the data collected is both actionable and accurate.
Independent Variables: The Inputs of Innovation
The independent variable is the “cause.” It is the factor that the engineer or researcher deliberately changes to observe what happens. In software development, this might be a new line of code, a different database indexing strategy, or a change in the user interface.
For instance, if a team at a streaming service wants to see if a new compression algorithm reduces buffering, the algorithm itself is the independent variable. They might test “Algorithm A” against the current “Algorithm B.” Because the researchers have direct control over which algorithm is deployed during the test, it is the independent variable. In the world of AI, an independent variable might be the learning rate of a neural network—a parameter that the developer adjusts to see how it influences the speed of convergence.
Dependent Variables: Measuring the Impact on Tech Performance
The dependent variable is the “effect.” It is the outcome that is measured to determine the success or failure of the experiment. This variable “depends” on the changes made to the independent variable. In tech, dependent variables are often equated with Key Performance Indicators (KPIs) or system metrics.
Continuing with the streaming service example, the dependent variables would likely be the “average buffering time per user” or “video start time.” If the independent variable (the new algorithm) is effective, the dependent variable (buffering time) should decrease. In digital security, if the independent variable is a new multi-factor authentication (MFA) protocol, the dependent variable might be the “rate of successful unauthorized login attempts.”
Control Variables: Maintaining Integrity in Software Testing
Control variables are the elements that remain constant throughout the experiment. In a complex digital environment, these are perhaps the most difficult to manage but are essential for eliminating “noise.” If control variables are not strictly maintained, the researcher cannot be certain if the change in the dependent variable was caused by the independent variable or by some other external factor.
In a software load test, control variables might include the server hardware, the network bandwidth, and the geographic location of the simulated users. If you change the code (independent variable) but also move the test from an on-premise server to a high-performance cloud instance, you have introduced a “confounding variable,” and your results are invalidated. You won’t know if the performance boost came from your code or the superior hardware.
Implementing Variables in A/B Testing and UI/UX Research
One of the most common applications of experimental variables in technology is A/B testing, often referred to as split testing. This is the gold standard for optimizing apps, websites, and SaaS platforms. By isolating variables, tech companies can make incremental improvements that lead to massive gains in user retention and engagement.
Identifying the Minimum Viable Change
In high-stakes tech environments, the temptation is to change multiple things at once—new colors, new fonts, and a new navigation menu. However, from an experimental standpoint, this is a failure of variable isolation. To gain clear insights, developers should focus on a “Minimum Viable Change.”
By changing only one independent variable at a time—for example, only the color of the “Sign Up” button—the team can definitively state that the resulting change in the click-through rate (the dependent variable) was caused by that specific visual update. This granular approach allows for a “winner-takes-all” development cycle where only the most effective features are integrated into the master branch.
Statistical Significance and Sample Size
In tech experiments, the dependent variable’s fluctuations must be evaluated through the lens of statistical significance. This determines whether the observed result is likely due to the change in the independent variable or if it occurred by pure chance.

Tech platforms have the advantage of “Big Data,” allowing for massive sample sizes. When testing a variable on a platform like a global social media app, an experiment can run on millions of users simultaneously. This high volume of data reduces the “margin of error,” making the relationship between the independent and dependent variables much clearer. Using tools like Bayesian statistics or P-value calculations, engineers can decide with high confidence whether to push a change to production.
Variables in Artificial Intelligence and Machine Learning Models
As we move into the era of AI-driven software, the management of variables becomes significantly more complex. In Machine Learning (ML), variables are not just binary switches; they are multi-dimensional data points that interact in non-linear ways.
Hyperparameters: The Meta-Variables of AI
In ML, we often distinguish between model parameters and hyperparameters. Hyperparameters are the variables that the developer sets before the training process begins. These include the number of hidden layers in a neural network, the batch size, and the dropout rate.
These function as the independent variables of the training experiment. By systematically varying these hyperparameters—a process known as hyperparameter tuning—developers can observe the impact on the model’s accuracy (the dependent variable). Because these variables are so numerous, tech teams often use “Grid Search” or “Random Search” algorithms to automate the experimentation process, essentially running thousands of mini-experiments to find the optimal configuration.
Training Data as a Variable
Perhaps the most influential variable in AI is the dataset itself. In an experiment to reduce bias in a facial recognition tool, the “diversity of the training images” becomes a critical independent variable. If the dependent variable is the “error rate across different demographic groups,” the developer must carefully control the composition of the training data to ensure that the AI learns to generalize correctly. In this context, data is not just a resource; it is a controlled variable that dictates the “intelligence” of the resulting software.
The Role of Confounding Variables in Digital Environments
In a perfect laboratory, every variable is accounted for. In the world of technology, however, “confounding variables” frequently threaten to skew data. A confounding variable is an outside influence that changes the effect of a dependent and independent variable.
External Noise: Seasonality and Server Latency
Imagine a tech company testing a new feature on their e-commerce app during the week of Black Friday. They see a 50% spike in conversions (dependent variable). If they attribute this entirely to their new feature (independent variable), they are ignoring a massive confounding variable: the holiday shopping season.
In digital infrastructure, server latency is another common confounding variable. If a developer is testing a new JavaScript framework to see if it improves page load speeds, but the test is conducted while the cloud provider is experiencing a regional outage, the latency will mask any improvements made by the code. Technical experiments must be designed to account for these external shocks, often by using “A/B/C” testing or by running “Control Groups” that are exposed to the exact same external conditions.
Bias in Algorithmic Experiments
In software that relies on user-generated data, “selection bias” can act as a confounding variable. If a new beta feature is only rolled out to “power users,” the data collected will be skewed because power users interact with tech differently than the general public. In this case, the “user profile” is a confounding variable that makes the new feature look more successful than it might actually be for a broader audience. Identifying and neutralizing these biases is essential for ensuring that tech products are inclusive and functional for all.
Scaling Success: From Variable Isolation to Full Deployment
The ultimate goal of identifying variables in tech experiments is to move from a state of hypothesis to a state of certainty. Once a variable has been proven to positively impact the dependent variable (the KPI), it can be integrated into the broader ecosystem.
Continuous Integration and Continuous Deployment (CI/CD)
Modern tech stacks utilize CI/CD pipelines to automate the testing of variables. Every time a developer commits code, it undergoes a series of automated experiments (unit tests, integration tests, and regression tests). In these automated environments, the code change is the independent variable, and the “build status” (Pass/Fail) is the dependent variable. This allows tech companies to experiment at scale, identifying bugs or performance regressions before they ever reach the end-user.

Creating a Culture of Experimentation
For a tech organization to remain competitive, it must foster a culture where every feature is viewed as a testable hypothesis. By training developers and product managers to think in terms of independent and dependent variables, companies can move away from “highest-paid person’s opinion” (HiPPO) decision-making and toward a purely data-driven model.
In conclusion, variables are the pulse of technological progress. By rigorously defining what we change, meticulously measuring what happens as a result, and vigilantly controlling for external noise, we can build software and AI that is not only functional but optimized for the complex, real-world environments in which it operates. Whether it is a minor CSS adjustment or a foundational change to a machine learning architecture, understanding the “what” and “why” of variables is the key to mastering the digital frontier.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.