
In the early decades of the computing revolution, technology was characterized by its rigidity. Software was a physical product shipped on disks, hardware lived in isolated server rooms, and data was stored in siloed, static repositories. It was a “solid-state” era where information moved slowly, if at all. Today, that paradigm has been entirely replaced by a fluid, interconnected environment that mimics the earth’s natural hydrological systems. When we ask “what water cycle” governs our modern world, we are increasingly referring to the digital water cycle: the continuous movement, evaporation, condensation, and precipitation of data across global networks.
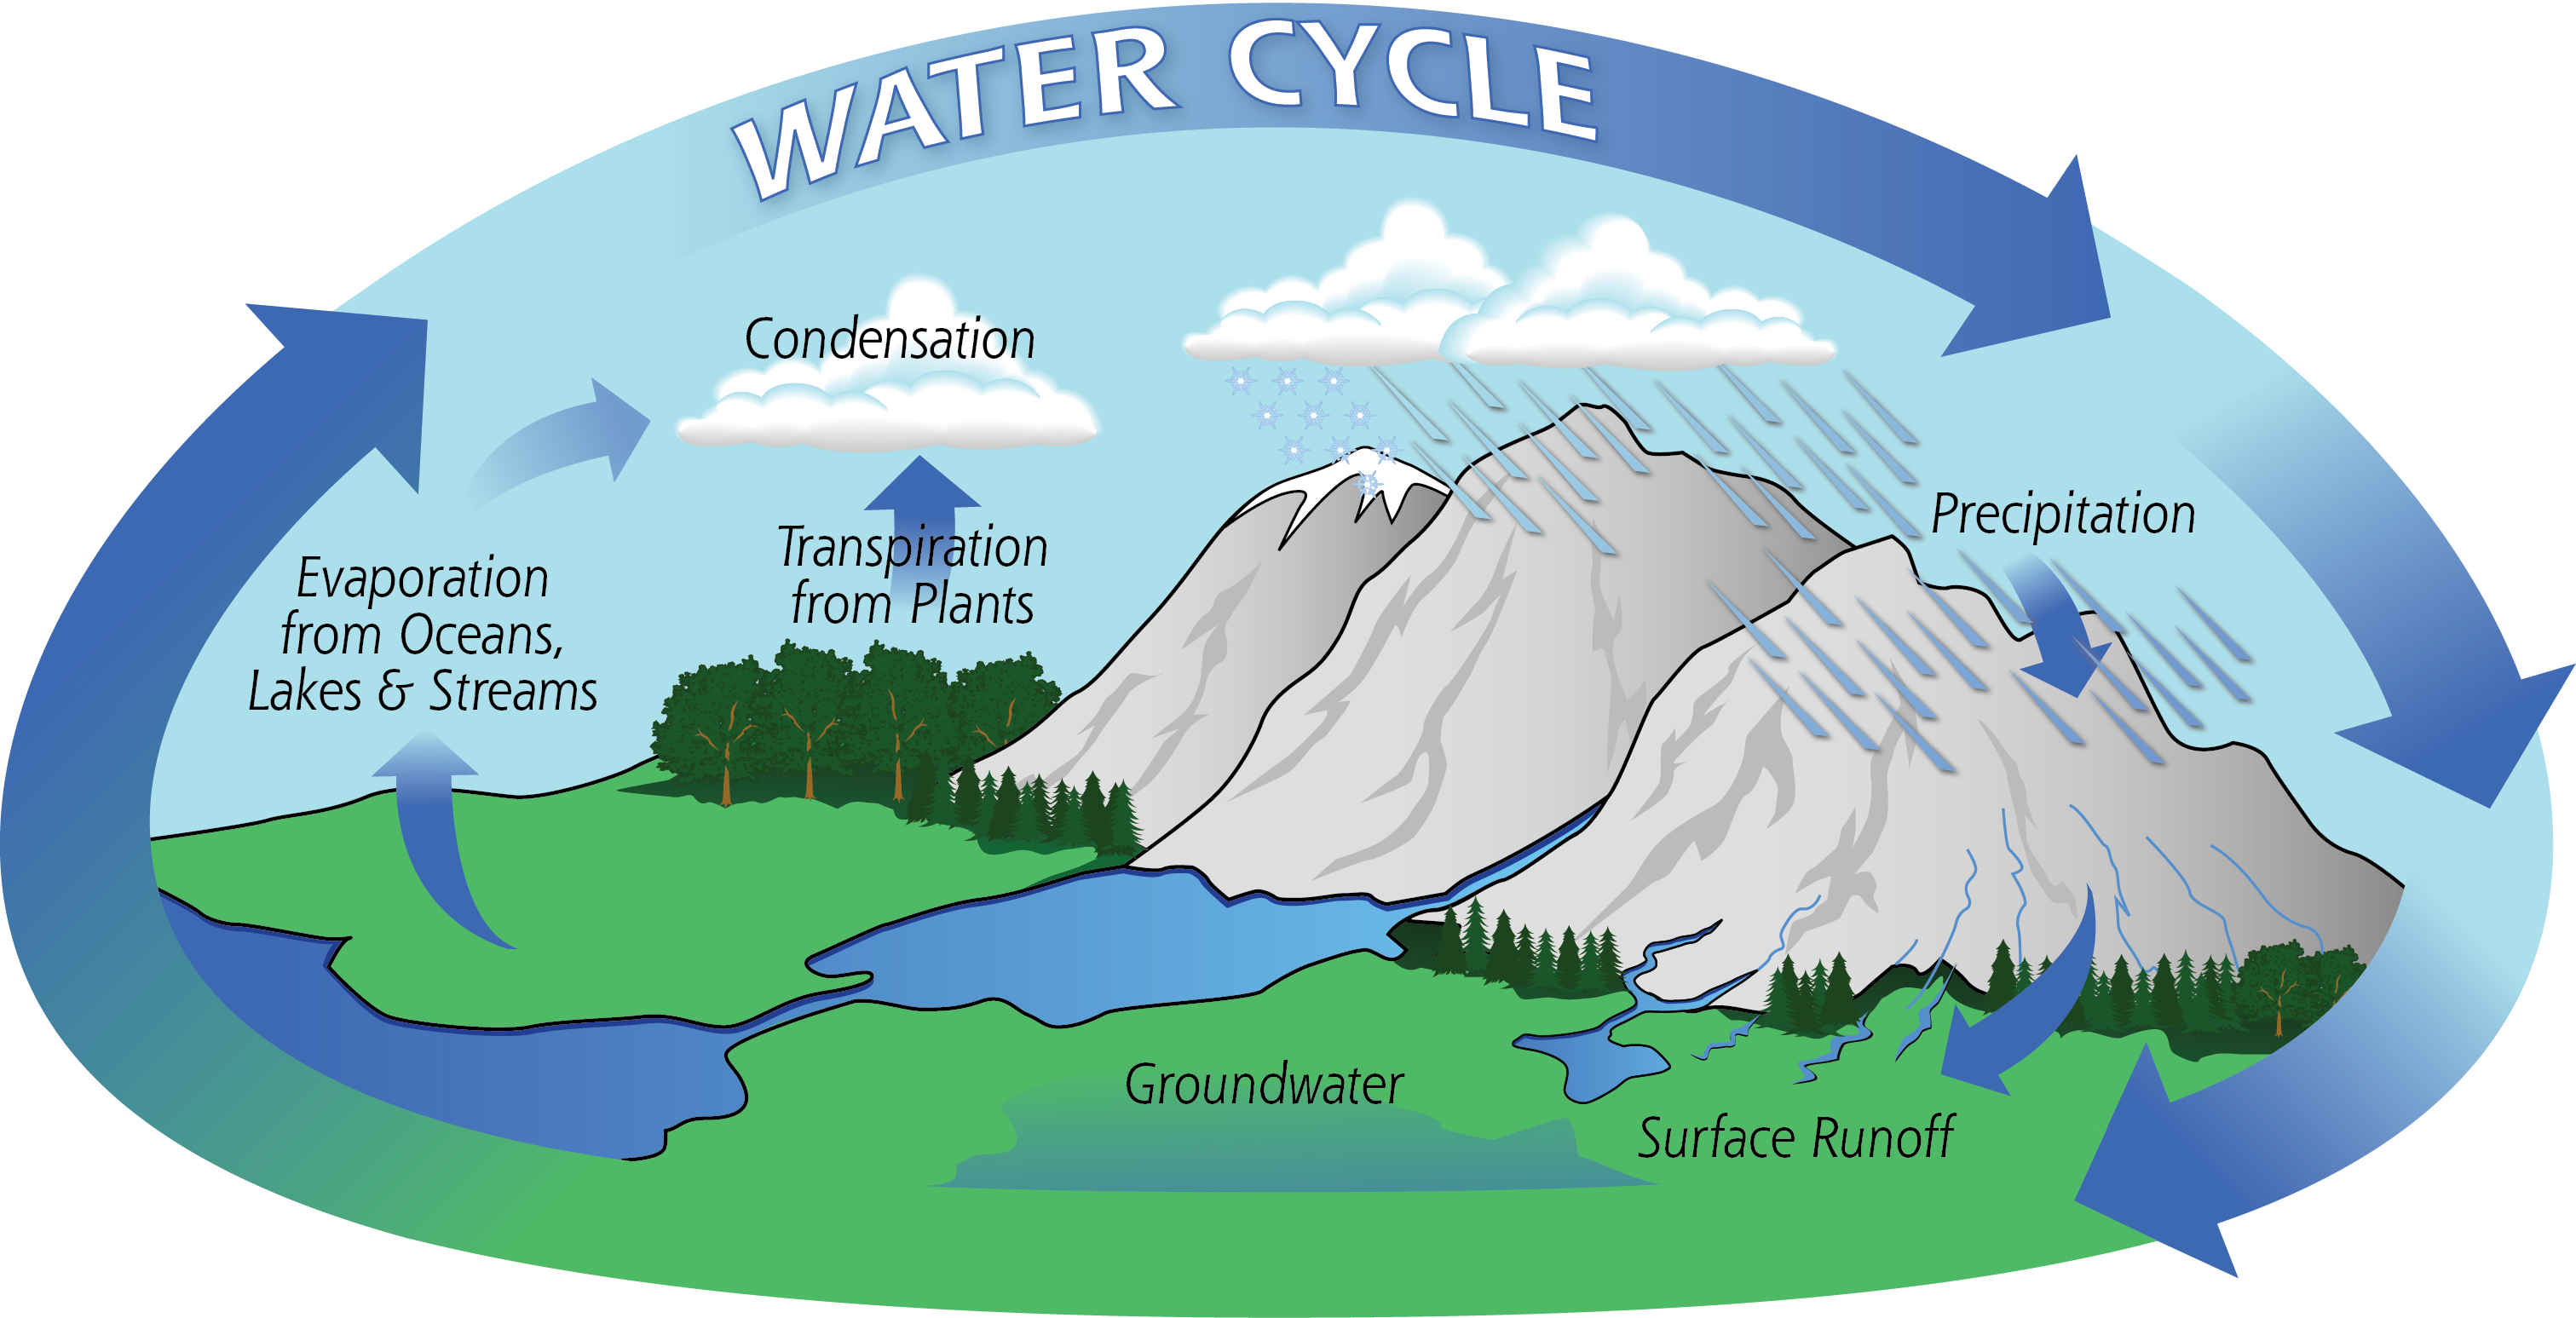
In this modern tech ecosystem, data is the lifeblood of every enterprise, but its value is no longer found in its accumulation. Instead, value is derived from its movement. Understanding the digital water cycle—how information flows from edge devices to the cloud, transforms through artificial intelligence, and precipitates back into actionable insights—is essential for any organization seeking to survive in a landscape defined by liquidity and speed.
The New Hydrology of Information: From Static Silos to Data Streams
The fundamental shift in modern technology is the move from batch processing to real-time streaming. In the past, data was collected and stored like stagnant water in a reservoir, waiting to be processed at the end of a week or month. Modern systems, however, rely on a “current” of information.
The Rise of Event-Driven Architecture
Event-driven architecture (EDA) represents the “river” phase of the digital water cycle. Instead of waiting for a central system to request information, individual components of a software ecosystem emit “events” as they happen. Whether it is a user clicking a button, a sensor detecting a temperature change, or a financial transaction being initiated, these events flow through the system in real-time. Technologies like Apache Kafka and Amazon Kinesis act as the channels for these flows, allowing different applications to “drink” from the stream of data as it passes by. This ensures that the entire tech ecosystem is reactive, responsive, and constantly in motion.
Data Liquidity and the API Economy
If data is water, then APIs (Application Programming Interfaces) are the plumbing that directs its flow. Data liquidity refers to the ease with which information can move between different platforms and services. In a high-liquidity environment, a company’s CRM can communicate seamlessly with its marketing automation tools, which in turn feed data into a predictive analytics engine. This interconnectedness prevents “digital droughts” where departments are starved of the information they need to make informed decisions. The API economy has turned every piece of software into a potential tributary, contributing to a larger, global body of information.
Cloud Infrastructure: The Reservoirs and Aquifers of the Digital Age
While data must flow, it also requires massive infrastructure to store and manage it. In our digital water cycle, cloud service providers like AWS, Microsoft Azure, and Google Cloud Platform serve as the global reservoirs. These are not merely storage bins; they are sophisticated management systems that ensure the availability, purity, and pressure of the data flow.
Data Lakes vs. Data Warehouses
The distinction between a data lake and a data warehouse is a perfect illustration of the digital hydrology metaphor. A data warehouse is like a municipal water treatment plant: it is structured, cleaned, and organized for specific purposes. It is ideal for operational reporting and historical analysis where the parameters are well-defined.
A data lake, conversely, is a vast, unstructured body of “raw” data. It stores everything in its natural state, from logs and images to social media feeds. The power of the data lake lies in its flexibility; because the data hasn’t been “filtered” yet, it retains all its original potential. Modern tech stacks often employ a “Lakehouse” architecture, which attempts to combine the scale of a lake with the structural integrity of a warehouse, ensuring that the organization can tap into both raw and refined resources as needed.
Elasticity and On-Demand Scaling
One of the most transformative aspects of the cloud is its elasticity. In a physical water cycle, a sudden surge in rainfall can cause a dam to overflow. In the digital world, cloud-native technologies allow the “reservoir” to expand its walls instantly. Through auto-scaling and serverless computing (such as AWS Lambda), the infrastructure grows or shrinks based on the volume of the data flow. This prevents system crashes during peak demand and ensures that resources are not wasted during dry spells, optimizing both performance and cost.
AI and the Evaporation Point: Transforming Raw Data into Intelligence
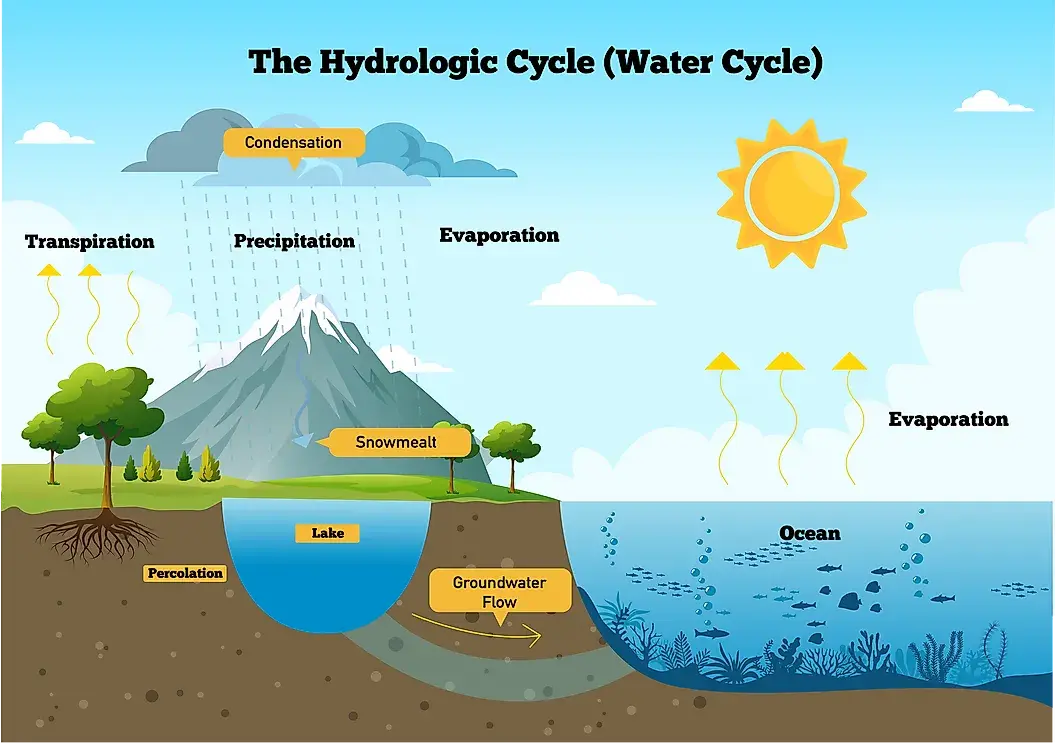
Perhaps the most critical phase of the digital water cycle is the transformation of raw information into “vapor”—the intangible yet powerful insights generated by Artificial Intelligence (AI) and Machine Learning (ML). This is where the “water” of data is heated by massive computational power, rising above the level of simple facts to become predictive intelligence.
The Training Cycle as Absorption
Machine learning models require immense amounts of data to function. This process is akin to the earth’s soil absorbing rainwater. Large Language Models (LLMs) and neural networks ingest trillions of data points, “absorbing” the patterns, linguistic nuances, and logical structures hidden within the noise. This absorption phase is resource-intensive, requiring specialized hardware like GPUs and TPUs to process the “moisture” of data and turn it into a trained model.
Inference and the Precipitation of Insights
Once a model is trained, it moves into the inference phase. This is the “precipitation” of the digital cycle. When a user asks an AI a question or a predictive algorithm identifies a fraud risk, the model is releasing the “water” it previously absorbed in a new, useful form. This precipitation is what drives modern digital experiences—personalized recommendations, autonomous driving decisions, and real-time language translation. Without this cycle of absorption and precipitation, data remains a heavy, inert mass; with AI, it becomes an atmospheric force that shapes the user experience.
Security Erosion and the Integrity of the Flow
Just as a natural water cycle can be threatened by pollution or infrastructure failure, the digital water cycle faces constant threats. Maintaining the purity and security of the data flow is the primary challenge for modern digital security teams.
Zero Trust: The Filtration System of the Future
In the old “castle and moat” model of security, once data was inside the network, it was trusted. Today’s fluid environment makes that model obsolete. Modern security has shifted toward “Zero Trust” architecture. This acts as a continuous filtration system. Every request for data, regardless of where it originates, must be verified, authenticated, and authorized. By treating every drop of data as potentially contaminated, organizations can prevent lateral movement by attackers and ensure that “leakage” (data breaches) is contained before it can flood the entire system.
Data Sovereignty and the Regulation of Flow
As data flows across international borders, it encounters different “climates” of regulation. Laws such as GDPR in Europe or CCPA in California act as environmental protections for the digital water cycle. They dictate how data can be collected, where it can be stored, and when it must be “deleted” (the digital equivalent of returning water to the earth). Tech leaders must now build “regulatory dams” and “filters” into their architecture to ensure they remain compliant while keeping the data flowing to the parts of the business that need it most.
Future-Proofing the Digital Watershed
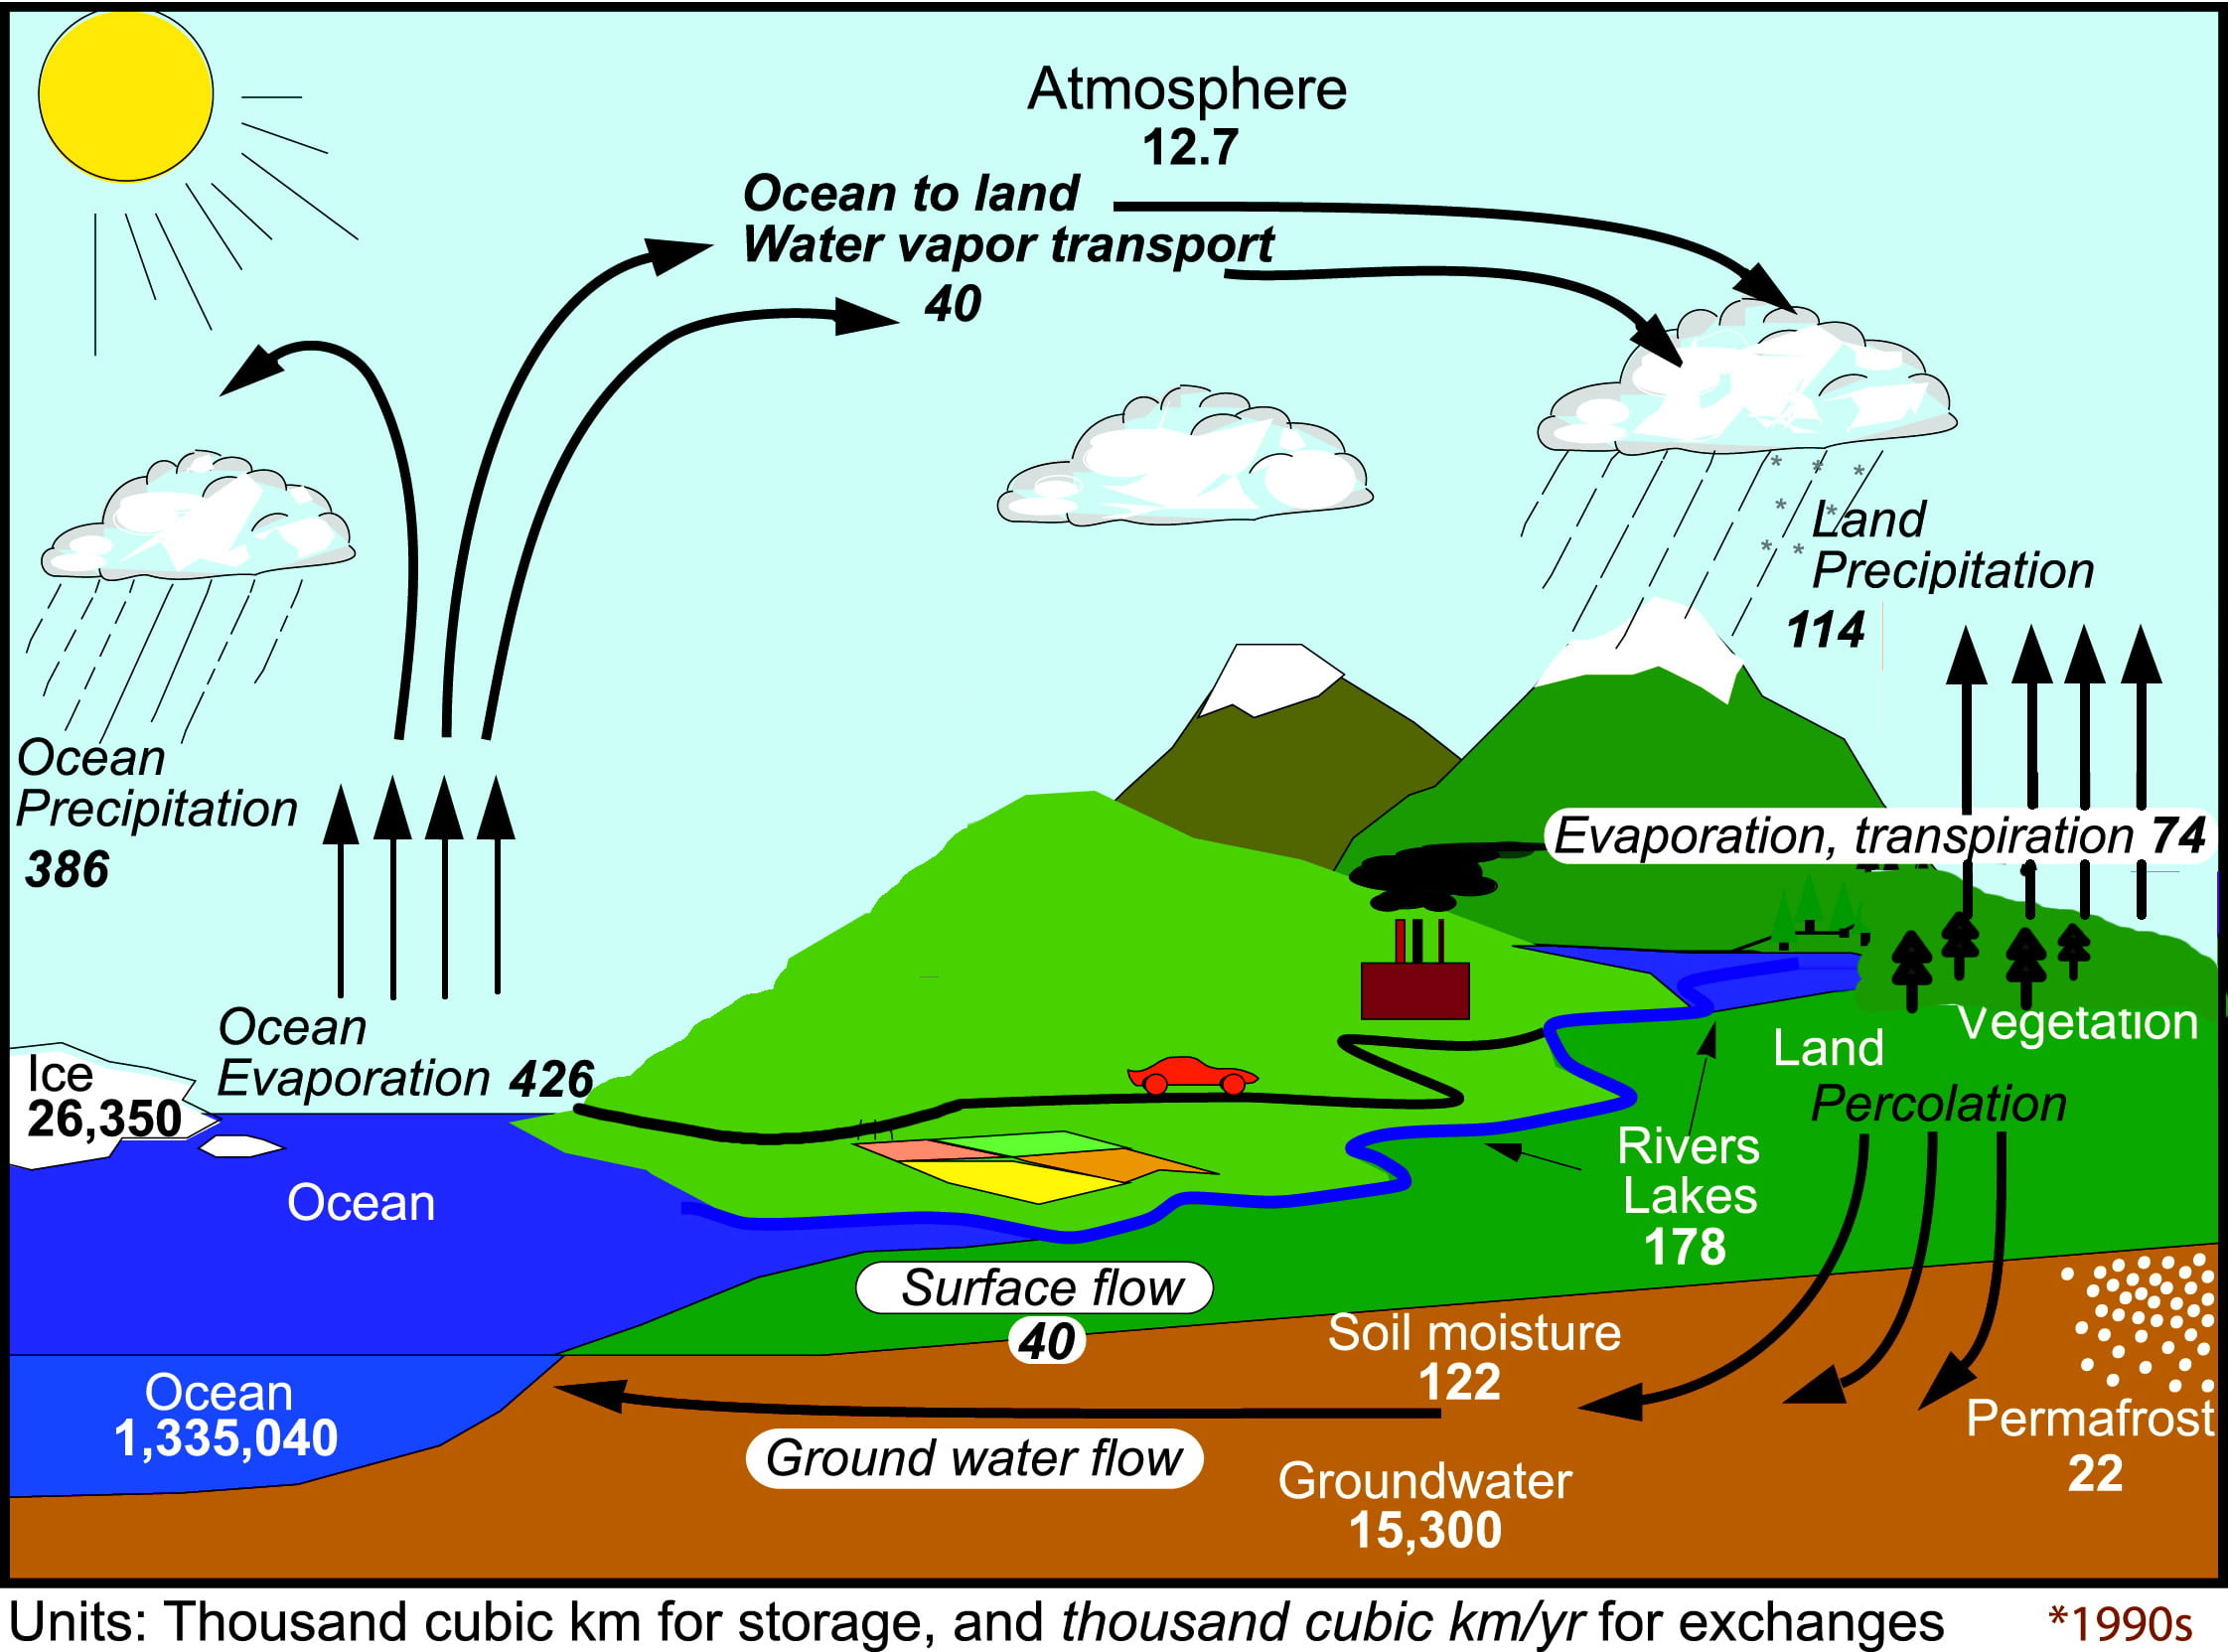
As we look toward the future, the digital water cycle is becoming even more complex. The emergence of Edge Computing is moving the cycle closer to the source—processing data at the “mountain peaks” of IoT devices before it ever reaches the cloud reservoirs. Meanwhile, Quantum Computing promises to heat the evaporation process to unprecedented levels, allowing us to solve problems that were previously “frozen” beyond our reach.
The organizations that will thrive in the coming decade are those that stop viewing technology as a collection of static tools and start viewing it as a dynamic, fluid system. They will invest in the “pipes” of high-speed connectivity, the “reservoirs” of scalable cloud storage, and the “filtration” of advanced cybersecurity.
“What water cycle?” is no longer a question for hydrologists; it is a fundamental question for Chief Technology Officers and software architects. By mastering the flow of information, the evaporation of data into intelligence, and the precipitation of insights into the market, businesses can ensure they remain resilient, sustainable, and productive in an increasingly liquid digital world. The cycle is constant, the flow is accelerating, and the opportunities for those who can navigate these digital waters are limitless.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.