
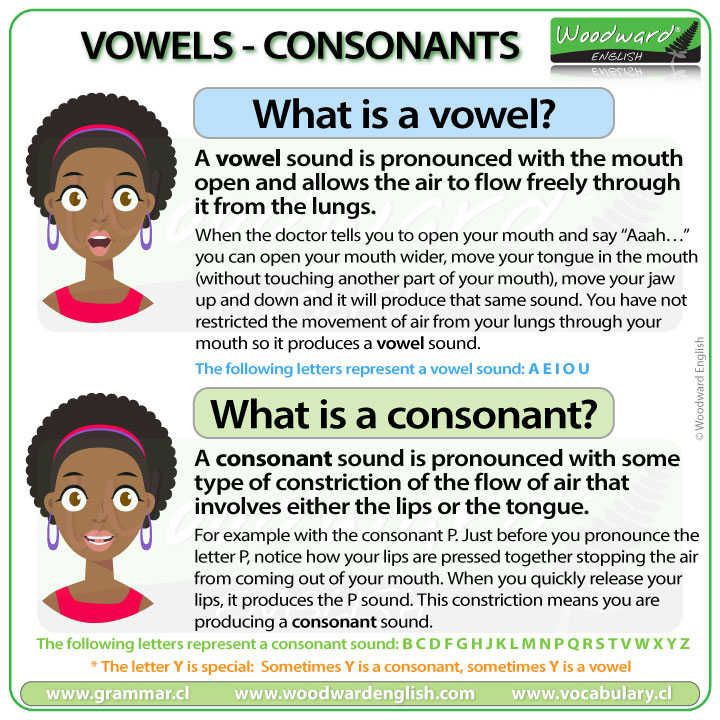
In the landscape of modern technology, particularly within the realms of Natural Language Processing (NLP) and Speech Synthesis, the concept of “the vowels” transcends its traditional grammatical definition. While a primary school student identifies vowels as the foundational letters A, E, I, O, and U, a software engineer or an AI researcher views them as complex spectral data points. In the digital age, vowels represent the fluid, resonant frequencies that allow machines to decode human intent, synthesize lifelike speech, and navigate the nuances of global dialects.

Understanding “the vowels” from a technological perspective is essential for comprehending how modern devices interpret sound. Unlike consonants, which are characterized by sudden bursts or friction-based interruptions of airflow, vowels are produced with an open vocal tract. This lack of obstruction creates a sustained, periodic waveform that is rich in data. For Artificial Intelligence, these waveforms are the keys to unlocking high-fidelity communication, making the study of digital phonetics a cornerstone of the next generation of tech tools.
The Linguistic Architecture of Machine Intelligence
To understand how tech platforms process language, one must first look at the transition from text-to-speech (TTS) to neural speech synthesis. Early digital voices sounded robotic because they struggled with the fluid transitions inherent in vowel production. Today’s AI models, such as those powering virtual assistants and automated translation tools, treat vowels as “formants”—specific frequency peaks of the spectrum of the human voice.
From Text-to-Speech to Neural Synthesis
In the early days of computing, “vowels” were treated as static assets. If a machine needed to say the word “Apple,” it would pull a pre-recorded snippet of the “A” sound and stitch it to the consonants. This resulted in the “uncanny valley” of audio, where the speech felt disconnected and jarring. Modern neural synthesis, exemplified by technologies like Google’s WaveNet or OpenAI’s Whisper, uses deep learning to predict the shape of a vowel based on its surrounding context.
Because vowels are the “glue” of language, modern AI must calculate the micro-transitions between a consonant and a vowel in real-time. This requires immense processing power and sophisticated algorithms that can simulate the physics of the human vocal tract. By understanding the mathematical properties of vowels, AI can now produce speech that includes emotional inflection, breathiness, and the subtle “color” that makes a voice sound human.
Why Vowels Matter in Machine Learning Models
In the context of machine learning, vowels are high-entropy data points. They carry the majority of the melodic information in a sentence. When a model is being trained on a dataset, it uses the spectral envelope of vowel sounds to identify the speaker’s gender, age, and even emotional state. This is critical for sentiment analysis tools used by corporations to gauge customer satisfaction in call centers. By analyzing the “stretching” or “compression” of vowel sounds, an AI can determine if a caller is frustrated, even if the words they use remain polite.
Optimizing for the Ear: The Intersection of Vowels and Voice SEO
As we move toward a “screenless” digital interaction model, Voice Search Optimization (VSO) has become a primary focus for developers and digital marketers. In this ecosystem, “the vowels” are the primary drivers of search accuracy. When a user asks a smart speaker a question, the device’s first task is to isolate the vowel sounds from the background noise to establish the phonetic framework of the query.
Beyond Keywords: Phonetic Query Matching
Traditional SEO relies on the exact spelling of words. However, voice-activated technology relies on phonetic matching. Because vowels are the loudest and most sustained parts of speech, they are the most likely to be captured clearly by a microphone in a noisy environment. Tech companies are now developing “phonetic indexes” where search results are categorized not just by their written form, but by their acoustic signature.
For developers creating apps, this means that brand names and navigation triggers must be “vowel-heavy” or acoustically distinct. A name with clear, open vowels (like “Alexa” or “Siri”) is much easier for an AI to distinguish from background static than a name heavy on sibilant consonants. This realization is shifting how software products are named and how user interfaces are designed for voice-first interactions.
Accents, Dialects, and Vowel Shift Challenges
One of the greatest hurdles in global tech deployment is the “Great Vowel Shift”—a linguistic phenomenon where vowel sounds evolve over time—and the vast array of modern regional accents. An AI trained exclusively on Californian English will often fail to recognize the vowels of a Scottish or Australian user.
To solve this, tech giants are investing in “Acoustic Diversity Training.” This involves feeding neural networks millions of hours of audio from diverse linguistic backgrounds. The goal is to create a “vowel-agnostic” AI that can map different phonetic realizations of the same word to a single digital concept. This is not just a matter of convenience; it is a matter of accessibility. Ensuring that a voice-controlled medical device or a security system can recognize vowels across all accents is a critical safety requirement in modern hardware design.
The Technical Challenge: Digital Signal Processing and Vowel Formants
At the hardware level, “what is the vowels” becomes a question of Digital Signal Processing (DSP). When sound enters a microphone, it is converted from an analog wave to a digital signal. Vowels appear as distinct patterns in a spectrogram, characterized by their “formants” (F1, F2, and F3).
The Spectral Shape of Sound: How AI “Sees” Vowels
When an AI “listens,” it isn’t hearing sound the way humans do; it is visualizing a spectrogram. Vowels are identified by the distance between their formants. For example, the vowel sound in “heed” has a low F1 and a high F2, while the vowel in “hot” has a much higher F1.
Modern AI tools use Fast Fourier Transforms (FFT) to break these sounds down into their constituent frequencies. By analyzing these formant positions, software can distinguish between similar-sounding words in milliseconds. This precision is what allows real-time transcription services to maintain high accuracy rates even when speakers are talking quickly. The “intelligence” in AI lies in its ability to predict what vowel should come next based on the probability of language patterns, a technique known as Markov modeling.
Wearable Tech and Edge Computing in Audio Processing
As we integrate AI into wearables like smart glasses and hearables, the processing of vowel data must happen “on the edge”—meaning locally on the device rather than in the cloud. This presents a massive engineering challenge: how do you perform complex spectral analysis of vowels on a low-power chip?
The solution has been the development of specialized Neural Processing Units (NPUs) optimized for audio. These chips are designed to recognize the “vowel signatures” of wake words (like “Hey Google”) using minimal energy. By focusing on the high-energy vowel frequencies, the device can stay in a low-power “sleep” mode, only fully activating when it detects the specific resonance of a recognized vowel pattern.
The Security Frontier: Phonetic Biometrics and Identity Verification
The unique way an individual produces vowels is as distinct as a fingerprint. This has led to the rise of voice biometrics, a field of digital security that uses phonetic patterns to verify identity.
The Vulnerability of Vowel-Based Deepfakes
As AI becomes better at synthesizing vowels, the threat of “deepfake” audio has increased. Since vowels provide the emotional and personal “texture” of a voice, malicious actors use generative adversarial networks (GANs) to mimic the specific vowel resonances of high-profile individuals. This poses a significant challenge for digital security and financial institutions that rely on voice verification.
In response, tech companies are developing “vowel-layer” authentication. This security measure looks for microscopic inconsistencies in how a synthesized voice transitions between vowels and consonants. While a deepfake might get the vowel sound right, it often struggles with the “co-articulation”—the way the vocal tract moves from one sound to the next.
Strengthening Authentication via Phonetic Patterns
To counter the rise of AI-generated fraud, multi-factor authentication is evolving to include “phonetic challenges.” Instead of a static password, a system might ask a user to repeat a specific phrase. The system then analyzes the “harmonic structure” of the vowels. Because human vocal folds produce natural jitter and shimmer (tiny variations in pitch and volume) that are difficult for current AI to replicate perfectly, the vowels become a biological firewall.
The future of tech is not just about what we say, but how we sound. By deconstructing “the vowels” into their digital components, the tech industry is creating a world where machines understand us with greater empathy, accuracy, and security. Whether it is a voice assistant in a smart home or a biometric security gate at an airport, the humble vowel is the invisible engine driving the next wave of digital innovation.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.