
In the landscape of modern technology, particularly within the realms of data science, artificial intelligence, and software architecture, the concept of “granularity” dictates how systems process, store, and interpret information. When we ask “what does coarsely chopped mean” in a technical context, we are referring to the intentional segmentation of data into large, high-level components rather than minute, intricate details. This “coarse” approach to data management and algorithm design is a fundamental strategy used to balance computational efficiency with analytical depth.
Understanding the distinction between coarse-grained and fine-grained processing is essential for developers, data architects, and tech leaders. As we move further into an era dominated by Large Language Models (LLMs) and massive cloud infrastructures, the decision to “chop” data coarsely or finely can determine the scalability, cost-effectiveness, and speed of a digital ecosystem.

The Architecture of Information: Defining Coarseness in Digital Data
To understand “coarsely chopped” data, one must first visualize the spectrum of data granularity. In software engineering and database management, granularity refers to the relative size or scale of the components that make up a system. A “coarsely chopped” system is one where the functional units are large, self-contained, and handle broad tasks.
From Bits to Bytes: The Spectrum of Granularity
At the most basic level, all digital information is fine-grained, existing as binary code. However, as we build abstractions on top of that code, we choose the “cut” of our data. Coarse-grained data might represent an entire customer profile or a complete transaction history as a single unit. Conversely, fine-grained data would break that profile down into individual attributes: name, timestamp of last login, specific item IDs in a cart, and millisecond-level interaction data.
The “coarsely chopped” approach is often preferred in the initial stages of data ingestion. When a system is dealing with petabytes of information, attempting to process every fine detail simultaneously leads to a “bottleneck effect.” By keeping the data in larger, coarse chunks, systems can move information through pipelines more rapidly, deferring the “fine-grained” analysis until it is absolutely necessary.
Why Data Resolution Matters for Scalability
In cloud computing and distributed systems, the “coarseness” of a service determines its overhead. Microservices architecture, for instance, often struggles with being “too finely chopped.” If every minor function of an application is its own independent service, the network latency between those services can degrade performance.
A “coarsely chopped” service architecture—sometimes referred to as “macro-services”—groups related functions into larger, more manageable units. This reduces the complexity of the communication web and allows for better resource allocation. For a growing tech company, knowing when to maintain a coarse structure versus when to refine it into smaller pieces is a critical strategic decision.
Tokenization and AI: The Art of “Chopping” Natural Language
The phrase “coarsely chopped” has found a specific home in the world of Natural Language Processing (NLP) and the development of AI models. For an AI to understand human language, it must first “chop” the text into smaller pieces called tokens.
Coarse-Grained vs. Fine-Grained Tokenization
Tokenization is essentially the process of chopping text. A “fine-grained” approach might involve character-level tokenization, where the AI looks at every single letter and punctuation mark. While precise, this is computationally expensive and makes it harder for the model to find long-range patterns in the text.
“Coarsely chopped” tokenization, on the other hand, involves word-level or even phrase-level segments. Most modern LLMs use a middle-ground approach called Subword Tokenization (like Byte Pair Encoding), but the “coarseness” of the vocabulary size remains a major design factor. If a model is trained on a “coarsely chopped” vocabulary, it recognizes large blocks of text as single units, which speeds up processing time and allows the model to “read” much faster.
The Efficiency Trade-off in Large Language Models
When building Retrieval-Augmented Generation (RAG) systems—which allow AI to look up specific information from a private database—developers must decide how to “chop” the source documents. If you chop a 100-page manual into “coarse” 2,000-word chunks, the AI gets a lot of context but might struggle to find a specific needle in the haystack.
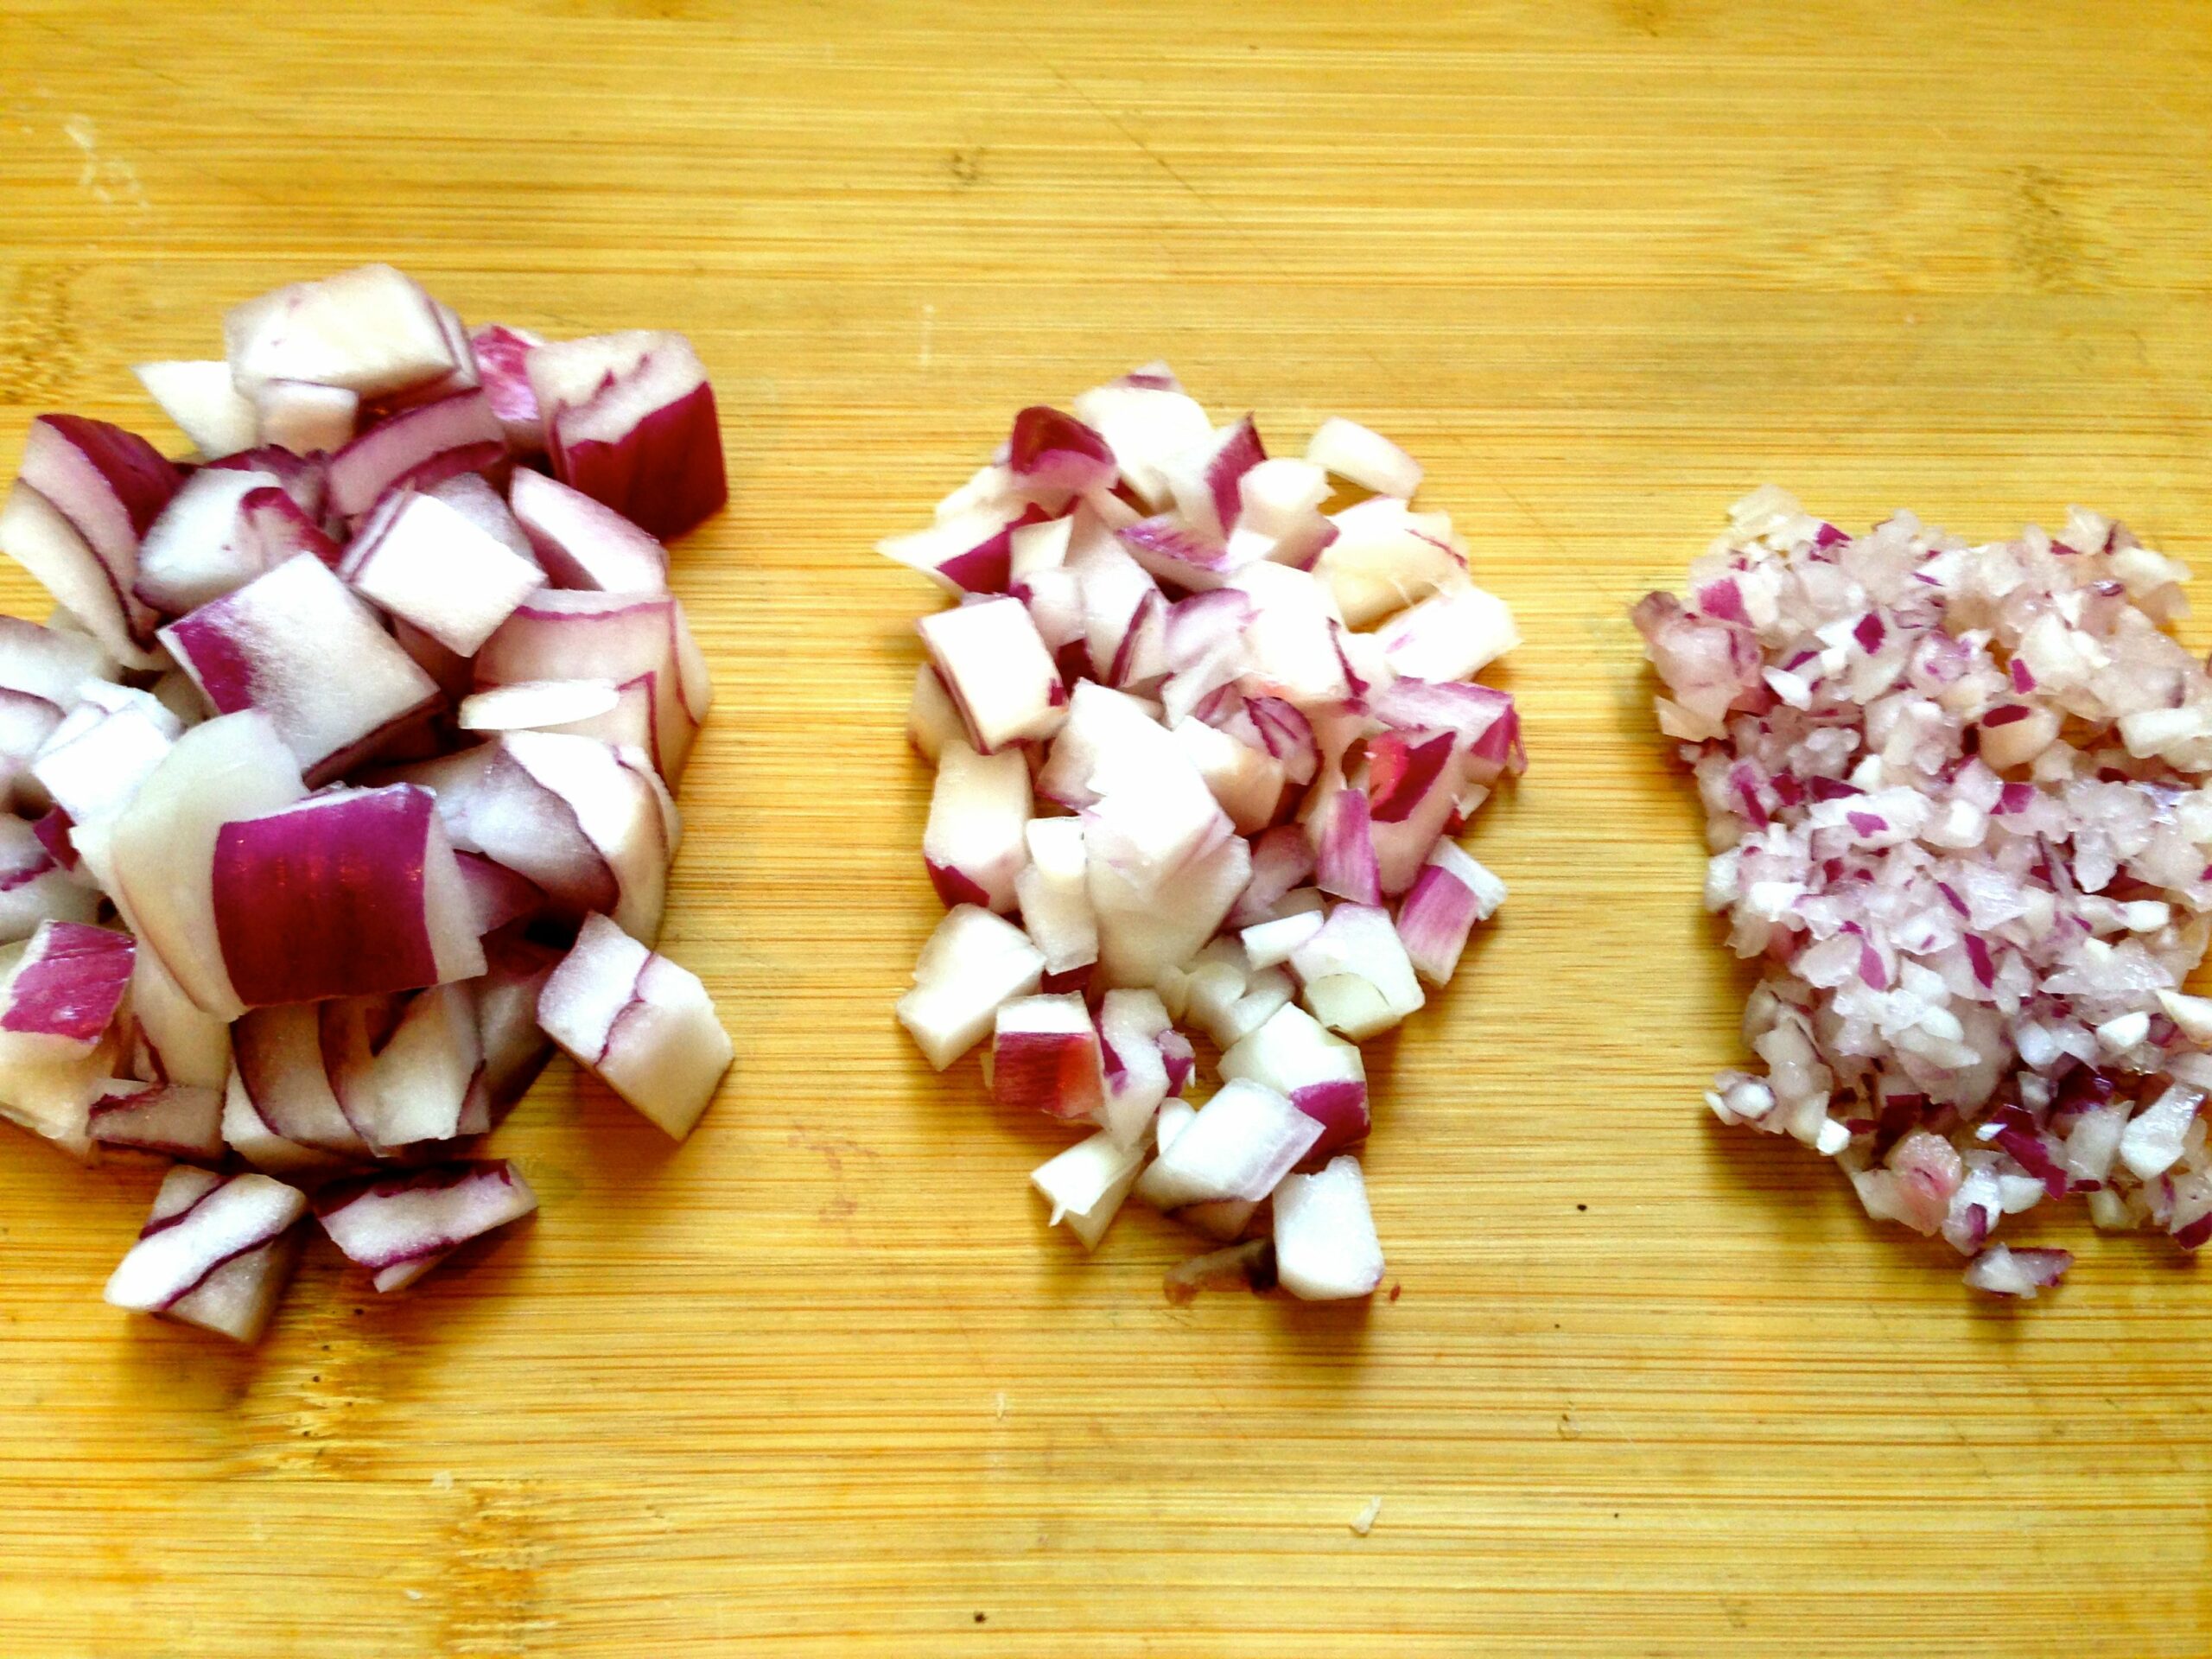
If you chop it into “fine” 50-word snippets, the AI finds the exact sentence quickly but lacks the surrounding context to understand what that sentence actually means. The “coarsely chopped” strategy in RAG is currently gaining favor for complex reasoning tasks where the relationship between ideas is more important than the individual words themselves.
Big Data Management: Coarsely Chopped Logic in Cloud Storage
In the world of Big Data and Data Warehousing (using tools like Snowflake, BigQuery, or Databricks), how data is “chopped” or partitioned dictates the cost of every query a business runs.
Data Lake Partitioning Strategies
When data enters a Data Lake, it is rarely organized. To make it searchable, architects use partitioning. A “coarsely chopped” partition might organize data only by “Year” or “Region.” This is efficient for storage because it requires very little metadata. However, if a user wants to find a specific transaction from 2:00 PM on a Tuesday, the system has to scan the entire “Year” chunk, which is slow and expensive.
The goal of modern data engineering is to find the “Goldilocks zone” of coarseness. By chopping data into manageable, mid-sized partitions, companies can optimize for “Data Pruning”—the ability of a database to ignore large chunks of irrelevant information and only focus on the “coarse” sections that likely contain the answer.
Search Optimization and Indexing Latency
Every time data is chopped more finely, the “index” (the map of where the data is) grows larger. In high-velocity tech environments, a massive, fine-grained index can become a liability. It takes time to update and time to search. By maintaining a “coarsely chopped” index, systems can achieve lower latency for broad searches. This is why “fuzzy search” algorithms often start with a coarse pass to narrow down the search space before applying a fine-grained filter to the results.
Security and Privacy: Anonymization through Coarse Data Aggregation
In the field of cybersecurity and data privacy, “coarsely chopping” information is not just about efficiency—it is a primary method for protecting user identity. This is often referred to as data masking or generalization.
Differential Privacy and Data Masking
When tech companies share data with researchers or advertisers, they must ensure that individuals cannot be “re-identified.” To do this, they “coarsen” the data. Instead of providing a specific birthdate (05/14/1992), they provide a coarse age range (30-35). Instead of a specific GPS coordinate, they provide a “coarsely chopped” geographic area like a zip code or a city district.
The “coarseness” of this data acts as a protective blur. The information is still useful for identifying broad trends (e.g., “users in this city like this app”), but it is too “coarsely chopped” to be used to track a single person.
Balancing Utility and Security
The challenge for tech firms is that the more “coarsely” they chop their data for privacy, the less “utility” or value that data has for precision targeting or diagnostic analysis. High-level tech strategy involves calculating the exact level of coarseness required to meet regulatory standards (like GDPR or CCPA) without rendering the data useless for the business’s core AI models.
The Future of Computational Efficiency: Refining the Coarse Approach
As we look toward the future of edge computing and the Internet of Things (IoT), the “coarsely chopped” philosophy is becoming even more vital. Edge devices, like smart cameras or industrial sensors, do not have the battery life or processing power to handle fine-grained raw data streams.
Instead, these devices are being programmed to “chop” data coarsely at the source. A smart security camera doesn’t send 24 hours of raw 4K video to the cloud; it uses a coarse algorithm to detect “motion” or “person,” and only then does it switch to a fine-grained mode to capture detail.
The tech industry is moving away from the “collect everything at the highest resolution” mindset and toward a “coarse-first” architecture. By understanding that “coarsely chopped” means prioritizing the macro over the micro, tech professionals can build systems that are faster, cheaper, and more private. Whether it is in the way we train our next-generation AI, the way we partition our global databases, or the way we protect user privacy, the art of the “coarse chop” remains a cornerstone of intelligent digital design.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.