
In an age saturated with information, the ability to pinpoint highly specific details rapidly and accurately has become a cornerstone of modern technological innovation. Queries that might once have required extensive manual research across multiple sources are now often answered within seconds, courtesy of sophisticated algorithms, vast databases, and intelligent agents. The seemingly simple request, “what episode does gus die in breaking bad,” serves as a potent microcosm for understanding the immense technological machinery working behind the scenes to deliver precise answers to niche queries across all domains. This article delves into the technological frameworks, tools, and methodologies that empower our digital ecosystems to not just find information, but to comprehend intent and provide direct, relevant insights, thereby transforming the user experience of discovery.
The Evolving Landscape of Information Discovery
The journey from primitive search functionalities to today’s intelligent information retrieval systems marks a profound evolution in how we interact with data. Early search engines, while revolutionary for their time, primarily relied on keyword matching and rudimentary indexing. A query for a specific plot point or character detail might yield thousands of pages, leaving the user to sift through them manually. The modern digital environment, however, has transcended this initial hurdle, moving towards a more intuitive, conversational, and precise mode of discovery.
From Manual Searches to Intelligent Agents
The initial phase of digital information retrieval was characterized by a push-and-pull dynamic: users pushed keywords, and systems pulled documents containing those keywords. This often resulted in information overload and a significant burden on the user to interpret and synthesize results. The advent of intelligent agents, powered by advancements in artificial intelligence and machine learning, fundamentally shifted this paradigm. These agents, whether integrated into search engines, virtual assistants, or specialized applications, are designed not just to match keywords but to understand the intent behind a query. They can infer context, recognize entities, and even anticipate subsequent questions, transforming the discovery process from a treasure hunt into a guided tour. This shift required a fundamental re-engineering of how data is indexed, analyzed, and presented, moving beyond mere lexical similarity to semantic understanding.
The Semantic Web and Knowledge Graphs
A critical enabler of this evolution is the concept of the Semantic Web and its practical manifestation in Knowledge Graphs. The Semantic Web, often envisioned as an extension of the current web, aims to make internet data machine-readable, allowing computers to understand the meaning (semantics) of information. Instead of just seeing text on a page, a machine can understand that “Gus Fring” is a character, “Breaking Bad” is a TV show, and “die” refers to a specific event within that show’s narrative.
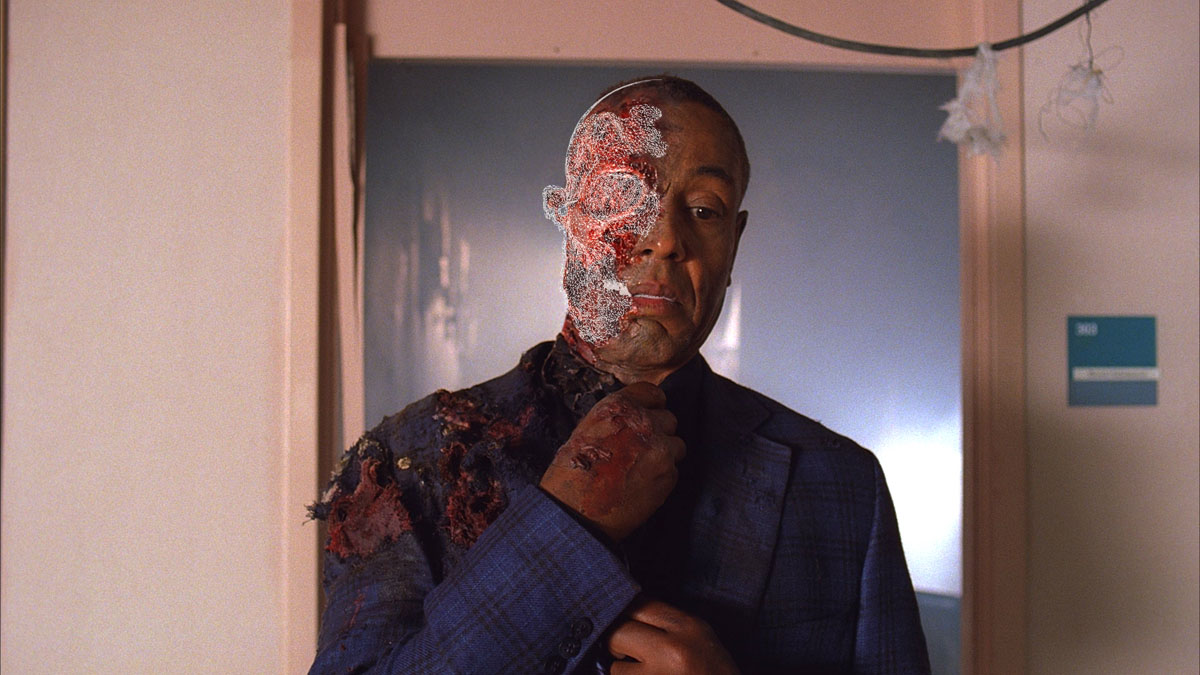
Knowledge Graphs are the structural backbone that brings the Semantic Web to life. These are large, interconnected databases that represent real-world entities (like characters, TV shows, events, and episodes) and the relationships between them in a graph format. For instance, a Knowledge Graph would explicitly state that “Gus Fring isacharacterin Breaking Bad,” and that “Gus Fring diesin_episode ‘Face Off’.” When a user asks “what episode does gus die in breaking bad,” the system doesn’t just look for those words; it navigates this graph, identifies the entities, finds the relationship, and extracts the precise value (the episode identifier). This structured, interconnected data model is indispensable for providing direct, factual answers without requiring the user to interpret a list of links.
AI’s Role in Pinpointing Specific Details
Artificial intelligence lies at the heart of modern information retrieval, empowering systems to understand, process, and respond to complex queries with unparalleled accuracy. The ability of AI to parse natural language, interpret context, and synthesize information from vast datasets is what makes direct answers to niche queries a reality.
Natural Language Processing (NLP) for Intent Understanding
At the core of AI-driven information retrieval is Natural Language Processing (NLP). NLP technologies enable machines to understand, interpret, and generate human language. When a user types or speaks “what episode does gus die in breaking bad,” an NLP engine goes far beyond simple keyword identification. It performs several sophisticated tasks:
-
Tokenization and Part-of-Speech Tagging: Breaking the sentence into individual words and identifying their grammatical roles (e.g., “what” as a determiner, “episode” as a noun, “die” as a verb).
-
Named Entity Recognition (NER): Identifying specific entities like “Gus” (person/character), “Breaking Bad” (creative work/TV show).
-
Relationship Extraction: Understanding the relationships between these entities and actions (e.g., “Gus” is associated with the act of “dying,” which occurs within “Breaking Bad”).
-
Intent Classification: Determining the user’s ultimate goal – in this case, seeking a specific factual piece of information (an episode number or title).
By combining these techniques, NLP transforms a casual query into a structured data request that the system can process against its Knowledge Graphs and databases, ensuring that the intent of the user is met, not just the literal string of words.
Generative AI and Conversational Interfaces
The advent of large language models (LLMs) and generative AI has further revolutionized how answers are delivered. Historically, systems might provide a list of search results or a snippet from a relevant page. Generative AI, however, can construct coherent, direct answers in natural language. Instead of presenting a link to a fan wiki page, a generative AI model can directly state, “Gus Fring dies in Season 4, Episode 13, titled ‘Face Off’.”
This capability is particularly powerful in conversational interfaces like chatbots, virtual assistants (e.g., Siri, Alexa, Google Assistant), and advanced search engines. These interfaces aim to mimic human conversation, providing succinct and relevant responses, often anticipating follow-up questions. The ability to generate contextually appropriate and factually accurate text from structured data sources (like Knowledge Graphs) is a hallmark of this advanced AI capability, making complex information accessible and digestible.
Fact Extraction and Verification in Dynamic Datasets
Providing a direct answer demands high confidence in its accuracy. For queries about evolving or highly detailed subjects, fact extraction and verification become paramount. AI models are trained to identify specific facts within unstructured text (like articles, reviews, or transcripts) and structured data. For example, by scanning a multitude of fan theories, episode summaries, and official show synopses, an AI can cross-reference information to confirm that Gus Fring’s death indeed occurs in a specific episode.
Furthermore, machine learning models are employed in a continuous loop of verification and updating. As new information emerges or existing data is corrected (e.g., a database entry error), these systems can identify discrepancies, prioritize trusted sources, and update their Knowledge Graphs accordingly. This dynamic capability ensures that the answers provided remain accurate and up-to-date, even for details within popular culture that might be subject to ongoing discussion or retrospective analysis.
The Infrastructure Powering Pop Culture Knowledge
Behind every instant answer to a niche query lies a robust and intricate technological infrastructure. This foundation comprises vast data storage solutions, sophisticated content management systems, and seamless integration protocols that allow diverse information sources to communicate and collaborate.
Massive Databases and Content Management Systems

To answer a query like “what episode does gus die in breaking bad,” systems rely on databases that hold an enormous volume of granular information. For popular culture, this includes details about every episode of every TV show, character biographies, plot summaries, production notes, and intricate relationships between them. These databases are often highly structured, using relational models or NoSQL architectures depending on the nature and scale of the data.
Complementing these are sophisticated Content Management Systems (CMS). For media companies, streaming platforms, and fan communities, CMS solutions are vital for ingesting, organizing, tagging, and publishing vast amounts of content. These systems allow for detailed metadata attachment – information about the information itself – which is crucial for precise retrieval. For instance, an episode entry in a CMS might include tags for all characters present, key plot points, themes, and specific events like a character’s death, making it highly searchable for AI and NLP engines.
API Integrations and Data Syndication
No single entity possesses all the world’s information. The ability to answer niche queries often depends on integrating data from multiple sources. Application Programming Interfaces (APIs) are the bridges that enable different software systems to communicate and share data. For example, a search engine might query an API from a major entertainment database (like IMDb or TVDB) to get definitive episode titles, air dates, and plot summaries. Streaming platforms leverage APIs to display detailed information about content to their users.
Data syndication, the process of supplying data to multiple customers, further enhances this ecosystem. Publishers of entertainment news, wikis, and content aggregators often consume syndicated data feeds to ensure their platforms are up-to-date. This interconnected web of data exchange, facilitated by standardized APIs, ensures that diverse platforms can collectively provide a comprehensive and accurate information landscape.
User-Generated Content and Collaborative Filtering
While official databases and expert-curated content form a significant part of the knowledge base, user-generated content (UGC) plays an increasingly critical role, particularly for niche and fan-centric queries. Platforms like Fandom wikis, Reddit threads, and community forums are rich repositories of highly specific, often crowd-sourced information. AI models and search algorithms are trained to index, analyze, and, importantly, verify information from these sources.
Collaborative filtering, a technique often used in recommendation systems, also implicitly aids in validating information. If hundreds or thousands of users agree on a specific detail (e.g., “Gus dies in this episode”), it adds weight to that piece of information. Advanced algorithms can discern consensus and identify authoritative voices within these communities, helping to filter out misinformation and elevate accurate details, thereby enriching the overall knowledge graph.
Beyond the Answer: Leveraging Query Data for Tech Innovation
The act of answering a query is just one facet of the technological utility derived from such interactions. The aggregate data from millions of specific queries, including niche ones, provides invaluable insights that fuel further innovation in personalization, content strategy, and user experience.
Personalization and Recommendation Engines
Every query, even one as specific as “what episode does gus die in breaking bad,” leaves a data footprint. This footprint, when analyzed in conjunction with other search behaviors, viewing habits, and explicit user preferences, significantly enhances personalization engines. If a user frequently searches for details about a particular show, recommendation systems can infer a strong interest in that genre, production company, or even specific actors, leading to more relevant content suggestions on streaming platforms or news feeds. This moves beyond broad categories to hyper-specific tastes, ensuring that users discover content they are genuinely likely to enjoy.
Predicting User Needs and Content Gaps
Analyzing patterns in niche queries can reveal emerging trends and identify gaps in existing content or information. If there’s a surge in queries about a character’s backstory that isn’t readily available, it signals a potential demand for new content (e.g., a spin-off, a detailed article, or an updated wiki entry). For media companies, this data is gold, guiding decisions on content creation, marketing strategies, and even intellectual property development. For information providers, it highlights areas where their knowledge base might need expansion or refinement, leading to more comprehensive and helpful resources.
Enhancing User Experience (UX) in Streaming and Media Platforms
The ultimate goal of many of these technologies is to create a seamless and intuitive user experience. For streaming platforms, this means making it incredibly easy to find specific content, understand character arcs, or recall plot points. Integrating AI-powered search, direct answers, and knowledge graphs directly into the platform’s interface reduces friction and enhances engagement. Users can quickly jump to relevant episodes, explore character profiles, or get answers to their burning questions without leaving the viewing environment. This not only improves satisfaction but also encourages deeper immersion and extended platform usage.
The Future of Niche Information Retrieval
The trajectory of information retrieval points towards even more sophisticated, proactive, and context-aware systems. The ability to answer “what episode does gus die in breaking bad” is just the beginning; the future promises a world where technology anticipates our informational needs with uncanny precision.
Hyper-Personalized Digital Assistants
Future digital assistants will evolve beyond reactive querying to become truly proactive and hyper-personalized. Leveraging advanced machine learning, they will learn individual user preferences, common queries, and even emotional states to offer information before it’s explicitly requested. For instance, knowing a user’s affinity for a particular show and their viewing habits, a digital assistant might proactively surface a relevant fan theory, a news article about an actor, or even the answer to an anticipated question without being prompted. These assistants will become integral parts of our cognitive workflow, seamlessly blending informational retrieval with our daily tasks and interests.

Multi-Modal Search and Contextual Understanding
While text-based queries are dominant today, the future of information retrieval will increasingly embrace multi-modal search. Users will be able to ask questions using a combination of voice, image, video, and even biometric data. Imagine pausing a scene, pointing to a character, and asking “what episode does this character die in?” The system would combine visual recognition with contextual understanding to provide the answer. Furthermore, the ability to understand nuanced context – including emotional tone, user history, and real-world environment – will allow systems to provide not just factual answers but also relevant insights and recommendations tailored to the specific situation, truly blurring the lines between information and intelligence.
In conclusion, the simple question “what episode does gus die in breaking bad” unravels a complex tapestry of technological advancements. From the intricate logic of Knowledge Graphs and the linguistic prowess of NLP to the generative capabilities of AI and the expansive infrastructure of databases and APIs, modern technology is designed to make sense of an ever-growing sea of data. This ongoing evolution ensures that accessing precise, niche information is not just possible but increasingly intuitive, enriching our digital interactions and transforming how we learn, discover, and engage with the world’s knowledge.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.