
In the intricate tapestry of technology, the term “socket” often conjures images of physical connection points—electrical outlets, network ports, or even CPU interfaces. However, within the vast ecosystem of digital infrastructure, the concept of a “socket” extends far beyond mere hardware. It represents any critical nexus where data flows, systems interact, or power is transmitted. When we ask, “what does a healing socket look like?” we delve into the fascinating realm of technological resilience, recovery, and the proactive measures designed to ensure continuous operation in an increasingly complex and interconnected world. It’s not about biological repair, but about the sophisticated processes, protocols, and architectural designs that allow technological components and systems to recover from failure, adapt to stress, and restore optimal functionality.
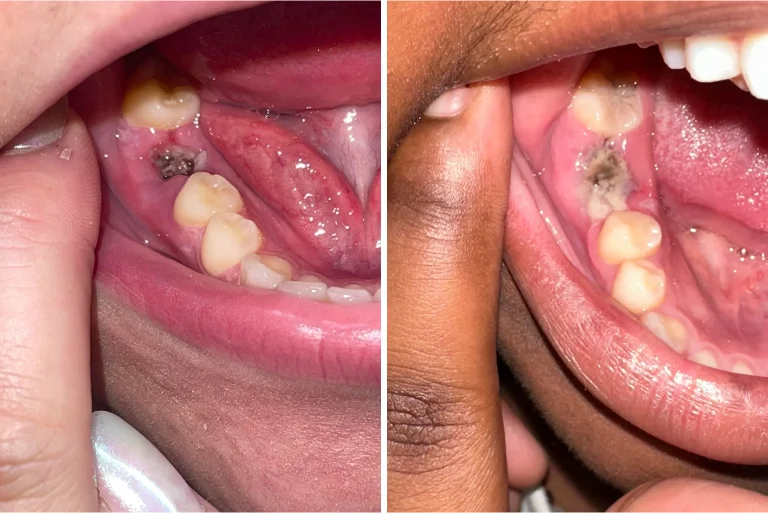
This exploration will transcend the literal to embrace the metaphorical, examining how various “sockets” within the tech landscape—from network communication endpoints to physical hardware connections and critical software APIs—demonstrate the hallmarks of recovery and robustness. A healing socket, in essence, embodies the principles of fault tolerance, self-correction, and intelligent restoration, ensuring the digital heartbeat of our modern world continues uninterrupted.
The Resilient Network Socket: A Digital Lifeline’s Recovery
In the digital domain, network sockets are the foundational communication endpoints. They are the gateways through which data packets flow between applications, servers, and users. A “healing” network socket signifies a connection that has encountered disruption—packet loss, latency spikes, or complete disconnection—and is now successfully recovering, stabilizing, and re-establishing reliable communication. Understanding this recovery process is crucial for maintaining seamless digital experiences.
Diagnosing the Digital Ailment: Identifying Network Socket Issues
Before a socket can heal, its ailment must be diagnosed. A network socket showing signs of distress might manifest as slow loading times, dropped connections, error messages (like “connection timed out”), or even complete service unavailability. Network administrators and developers employ a suite of tools and metrics to pinpoint these issues. These include:
-
Ping and Traceroute: Basic utilities to check connectivity and trace the path data takes, identifying where delays or losses occur.
-
Packet Analyzers (e.g., Wireshark): Deep packet inspection reveals malformed packets, retransmissions, and protocol errors that indicate a struggling socket.
-
Network Performance Monitoring (NPM) Tools: These platforms continuously track metrics like latency, jitter, bandwidth utilization, and error rates, often presenting them visually on dashboards. Spikes in error rates or drops in throughput signal an unhealthy socket.
-
Log Analysis: Server and application logs can provide clues about connection failures, refused connections, or authentication issues related to specific sockets.
A “healing” network socket, therefore, begins to look like a gradual normalization of these metrics: dropped packets cease, latency returns to baseline, and connection errors diminish, indicating that underlying issues—be they routing problems, congested links, or server-side glitches—are being resolved.
Self-Healing Protocols and Architectures: Engineering for Recovery
The internet’s inherent resilience owes much to its foundational protocols and modern architectural patterns that build self-healing capabilities directly into the system.
-
TCP/IP’s Built-in Resilience: At a fundamental level, TCP (Transmission Control Protocol) is a prime example of a self-healing mechanism. When packets are lost or arrive out of order, TCP automatically requests retransmission and reassembles them correctly, ensuring reliable data delivery. This constant error checking and correction is a continuous “healing” process, preventing minor network glitches from causing outright connection failure.
-
Software-Defined Networking (SDN) and Network Automation: SDN allows for dynamic, programmatic control of network infrastructure. In a healing scenario, SDN controllers can automatically detect link failures, reroute traffic around congested areas, or provision new network paths to restore connectivity without human intervention. This automated response is a sophisticated form of network socket self-healing.
-
Container Orchestration (e.g., Kubernetes): In cloud-native environments, platforms like Kubernetes manage containerized applications. If a pod (which exposes network sockets for its services) fails, Kubernetes can automatically detect the failure, terminate the unhealthy pod, and spin up a new, healthy instance, effectively “healing” the service availability by replacing a broken socket with a functional one. Load balancers then seamlessly redirect traffic to the new healthy socket.
Visualizing Network Health: The Look of a Recovering Socket
For engineers, a healing network socket translates into specific visual cues on monitoring dashboards:
-
Green Status Indicators: What was red or amber (indicating an issue) slowly transitions back to green, signifying operational health.
-
Normalized Graphs: Spikes in latency, packet loss, or error rates on graphs begin to trend downwards, returning to their expected steady state. Throughput graphs, which may have plummeted during an outage, show a steady upward climb back to normal levels.
-
Decreased Alert Volume: The deluge of alerts triggered by the problem gradually subsides, indicating that the system is stabilizing and the thresholds for healthy operation are being met again.
-
Consistent Application Performance: End-user monitoring tools show faster response times and fewer errors, confirming that the underlying network sockets are no longer impacting the user experience.
The “look” of a healing network socket is one of returning stability, with data flowing freely and efficiently through restored digital channels, often without the end-user ever realizing a problem occurred.
Hardware Socket Restoration: From Physical Damage to Functional Revival
While network sockets operate in the realm of bits and bytes, hardware sockets represent tangible physical connections that can also suffer damage and undergo a “healing” process—though often involving human intervention rather than purely automated means. These are the critical junctures where components physically interface, and their integrity is paramount for system functionality.
The CPU Socket: A Delicate Recovery
Perhaps one of the most critical and delicate hardware sockets is the CPU socket on a motherboard. Bent pins, thermal damage, or physical impact can render a CPU socket inoperable, preventing the entire computer from booting. The “healing” of a CPU socket is a highly skilled operation:
-
Pin Straightening: For PGA (Pin Grid Array) sockets where the CPU has pins, bent pins can sometimes be meticulously straightened using specialized tools (magnification, fine tweezers, or even a razor blade). This is a manual, intricate repair that physically restores the connection.
-
BGA Re-balling (for BGA sockets): For LGA (Land Grid Array) sockets on the motherboard or BGA (Ball Grid Array) packages where the CPU or other chips are soldered directly, damage might require re-balling. This involves removing the chip, cleaning the pads, applying new solder balls, and precisely re-soldering it back onto the board. It’s a complex, specialized “surgical” procedure to restore hundreds or thousands of tiny electrical connections.
-
Socket Replacement: In severe cases, the entire CPU socket component might need to be desoldered and replaced with a new one.
The “look” of a healing CPU socket is the transformation from a visibly damaged, non-functional component to a pristine, re-soldered, and fully operational interface that successfully allows the CPU to boot and function as intended. It represents precision repair bringing a critical hardware component back to life.
Electrical Sockets and Smart Home Resilience: Ensuring Power Continuity
Literal electrical sockets are fundamental to powering our devices. While typically robust, they can suffer from wear, improper wiring, or damage from power surges. In the context of “healing,” this can involve:
-
Smart Socket Diagnostics: Modern smart plugs and power strips often incorporate diagnostic capabilities, monitoring voltage fluctuations, current draw, and even detecting faulty grounding. They can self-diagnose minor issues or alert users to potential electrical problems.
-
Surge Protection and Circuit Breakers: These are passive “healing” mechanisms. A surge protector sacrifices itself to absorb a damaging power spike, preventing it from reaching the connected devices (and implicitly, the wall socket). Circuit breakers automatically trip to prevent overheating and fire, effectively “healing” a potentially dangerous overload by breaking the circuit, requiring manual reset.
-
Professional Repair and Rewiring: For truly damaged or faulty electrical sockets, the “healing” looks like the careful replacement of the outlet, re-termination of wires, and testing by a qualified electrician to ensure safety and proper functionality.
A healing electrical socket looks like a safe, stable power delivery point, free from scorch marks, loose connections, or intermittent power delivery, often ensured by smart technology or professional intervention.
The Art of Hardware Diagnostics and Repair: Human-Driven Healing
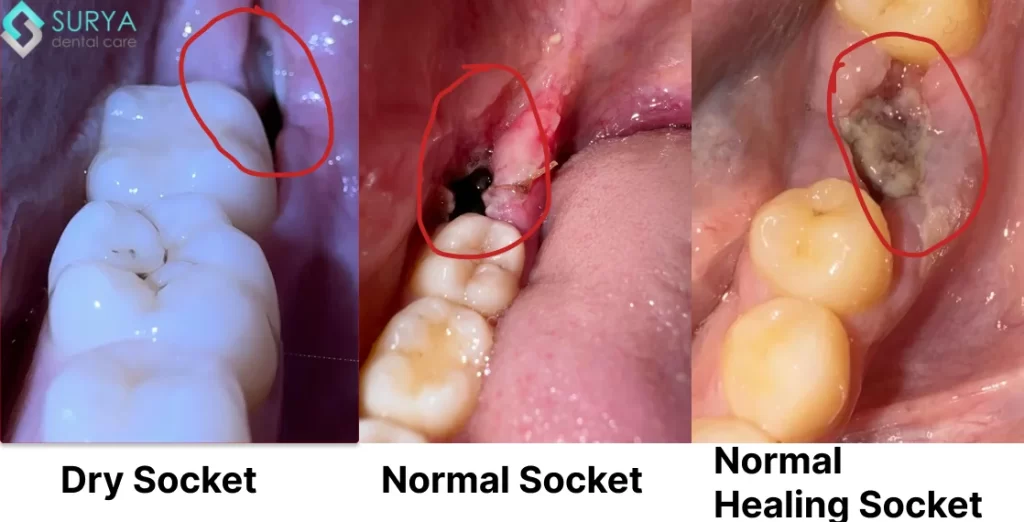
For many hardware sockets, the “healing” process is less automated and more reliant on skilled technicians. This involves:
-
Visual Inspection: Looking for physical damage, corrosion, or wear.
-
Multimeter Testing: Checking for continuity, correct voltage, and resistance across the socket’s pins or terminals.
-
Component Swapping: Systematically replacing suspected faulty components (and their associated sockets) to isolate the problem.
A successfully “healed” hardware socket, whether a USB port, a memory DIMM slot, or a PCIe expansion slot, is one that has been painstakingly restored to its original specifications, allowing the connected component to operate flawlessly and reliably within the larger system.
Software Sockets and API Resilience: Mending the Code’s Connections
In the world of software, the concept of a “socket” often extends metaphorically to Application Programming Interfaces (APIs). APIs are the crucial “connection points” that allow different software systems, services, and applications to communicate and exchange data. A “healing” software socket, or API, refers to its ability to recover from internal errors, external service outages, or unexpected data inputs, maintaining robust and reliable communication pathways.
APIs as Integration Sockets: The Digital Handshake
APIs are the backbone of modern interconnected applications, from microservices architectures to third-party integrations. Each API endpoint acts as a “socket” for sending and receiving requests and responses. When these “sockets” are unhealthy, the entire application or service can fail. Common ailments include:
-
Network Latency or Outages: The underlying network socket can impact API performance.
-
Service Unavailability: The service providing the API might be down.
-
Internal Server Errors: Bugs or resource contention within the API’s own code.
-
Malformed Requests: Invalid data or authentication issues from the calling client.
-
Rate Limiting: Excessive requests leading to temporary denial of service.
A healing API is one that can navigate these challenges, ensuring data exchange remains possible or gracefully fails without crashing the entire system.
Building Self-Healing APIs and Microservices: Code for Robustness
Modern software development emphasizes building resilience directly into API design and microservices architecture. This “self-healing” capability is achieved through several design patterns:
-
Robust Error Handling and Logging: APIs should anticipate and gracefully handle various error conditions, returning informative error messages without exposing sensitive data. Comprehensive logging allows developers to diagnose issues quickly.
-
Circuit Breakers: This pattern prevents an application from repeatedly trying to access a failing remote service. If an API “socket” consistently fails, the circuit breaker “trips,” preventing further calls for a period. After a timeout, it attempts to “half-open” the circuit to see if the service has recovered, effectively “healing” the repeated failure cycle.
-
Retry Mechanisms: When an API call fails due to transient issues (e.g., a brief network glitch), the client can automatically retry the request after a short delay, often with an exponential backoff strategy. This allows the API “socket” to heal from temporary disruptions.
-
Idempotency: Designing API endpoints such that making the same request multiple times has the same effect as making it once. This is crucial for safely retrying requests without unintended side effects.
-
Automated Rollbacks: In continuous deployment pipelines, if a new API version introduces critical bugs, automated systems can detect the failure (often via monitoring of the API “socket” health) and roll back to the previous, stable version, effectively “healing” the API’s functionality.
-
Load Balancing and Redundancy: Distributing requests across multiple instances of an API service ensures that if one instance fails, others can pick up the load, maintaining the overall health of the API “socket” cluster.
Observability and Anomaly Detection in Software Sockets
For developers and operations teams, understanding a healing software socket involves comprehensive observability:
-
API Monitoring Dashboards: Visualizing request rates, error rates (e.g., 5xx errors), latency, and throughput for each API endpoint. A healing socket will show error rates declining, latency normalizing, and throughput returning to expected levels.
-
Distributed Tracing (e.g., OpenTelemetry): Tracking individual requests as they propagate through multiple microservices and APIs provides a detailed view of where delays or failures occur. A healing trace shows successful completion through all services.
-
Alerting Systems: Configured to notify teams when API health metrics breach predefined thresholds, triggering investigation and intervention. The absence of these alerts indicates a healthy, or healing, state.
-
Synthetic Monitoring: Periodically sending simulated requests to API endpoints from external locations to proactively check their availability and performance, giving an outside-in view of health.
The “look” of a healing software socket is the seamless, reliable, and predictable flow of data and commands through APIs, underpinned by intelligent code, robust architectural patterns, and vigilant monitoring, ensuring application functionality even in the face of adversity.
The Future of Self-Healing Systems: Proactive Resilience
The evolution of “healing sockets” in technology is moving towards more proactive, predictive, and autonomous systems. The goal is not just to react to failures but to anticipate and prevent them, or to recover so quickly and seamlessly that the impact is negligible.
AI and Machine Learning in Predictive Healing
Artificial Intelligence and Machine Learning are at the forefront of this evolution. By analyzing vast amounts of operational data, AI can:
-
Predict Failures: Machine learning models can identify subtle anomalies and patterns that precede system failures, allowing for preventative action (e.g., patching a server, scaling up resources) before a “socket” breaks.
-
Automated Root Cause Analysis: AI can rapidly sift through logs and metrics to pinpoint the exact cause of an issue, significantly accelerating the healing process.
-
Intelligent Resource Allocation: AI-driven systems can dynamically adjust resources (CPU, memory, network bandwidth) to prevent bottlenecks that might lead to “socket” failures, ensuring continuous optimization.
-
Self-Optimizing Networks: AI can learn network traffic patterns and automatically reconfigure routing or adjust bandwidth to prevent congestion and optimize performance, constantly “healing” the network’s efficiency.
Autonomous Operations and Chaos Engineering
The ultimate vision for healing sockets involves systems capable of fully autonomous operations, where recovery happens without human intervention.
-
Autonomous Incident Response: AI agents could automatically execute predefined recovery playbooks, restart services, or failover to redundant systems when issues are detected.
-
Chaos Engineering: This practice involves intentionally injecting failures into a system in a controlled environment to test its resilience. By observing how “sockets” break and heal under stress, engineers can identify weaknesses and strengthen the system’s ability to recover proactively. A system that gracefully endures chaos engineering experiments demonstrates a highly evolved capacity for self-healing.
The Human Element in System Recovery
While automation is increasing, the human element remains crucial. Engineers, Site Reliability Engineers (SREs), and DevOps teams design, build, and continuously refine these self-healing mechanisms. They analyze complex incidents, update recovery protocols, and ensure that the systems are not just reacting but learning and evolving. The “look” of a healing socket often includes the rapid, intelligent response of these teams, guided by data and empowered by automated tools.

Conclusion
When we ponder “what does a healing socket look like?”, we unlock a multifaceted understanding of resilience in the digital age. It’s a journey from the tangible repair of a physical CPU socket to the intricate dance of packets restoring a network connection, and further into the intelligent recovery mechanisms of software APIs. A healing socket represents more than just fixing what’s broken; it embodies the proactive design, the intelligent automation, and the continuous monitoring that characterize robust technological systems. It looks like stability returning, functionality resuming, and an often-invisible triumph over the inherent fragility of complex systems. As technology continues its relentless march forward, the capacity for our “sockets” to heal, adapt, and self-restore will remain paramount, ensuring the uninterrupted flow of information and innovation that defines our modern world.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.