
In the landscape of modern technology, the term “discharge” is often associated with the movement of energy or data from a source to a destination. While a healthy flow of information and power is the lifeblood of any digital ecosystem, “unhealthy discharge” represents a critical failure point. Whether it manifests as a rapid battery drain in a mobile device, a data leak in a cloud environment, or memory mismanagement in software architecture, identifying the signs of unhealthy digital discharge is essential for engineers, developers, and security professionals.
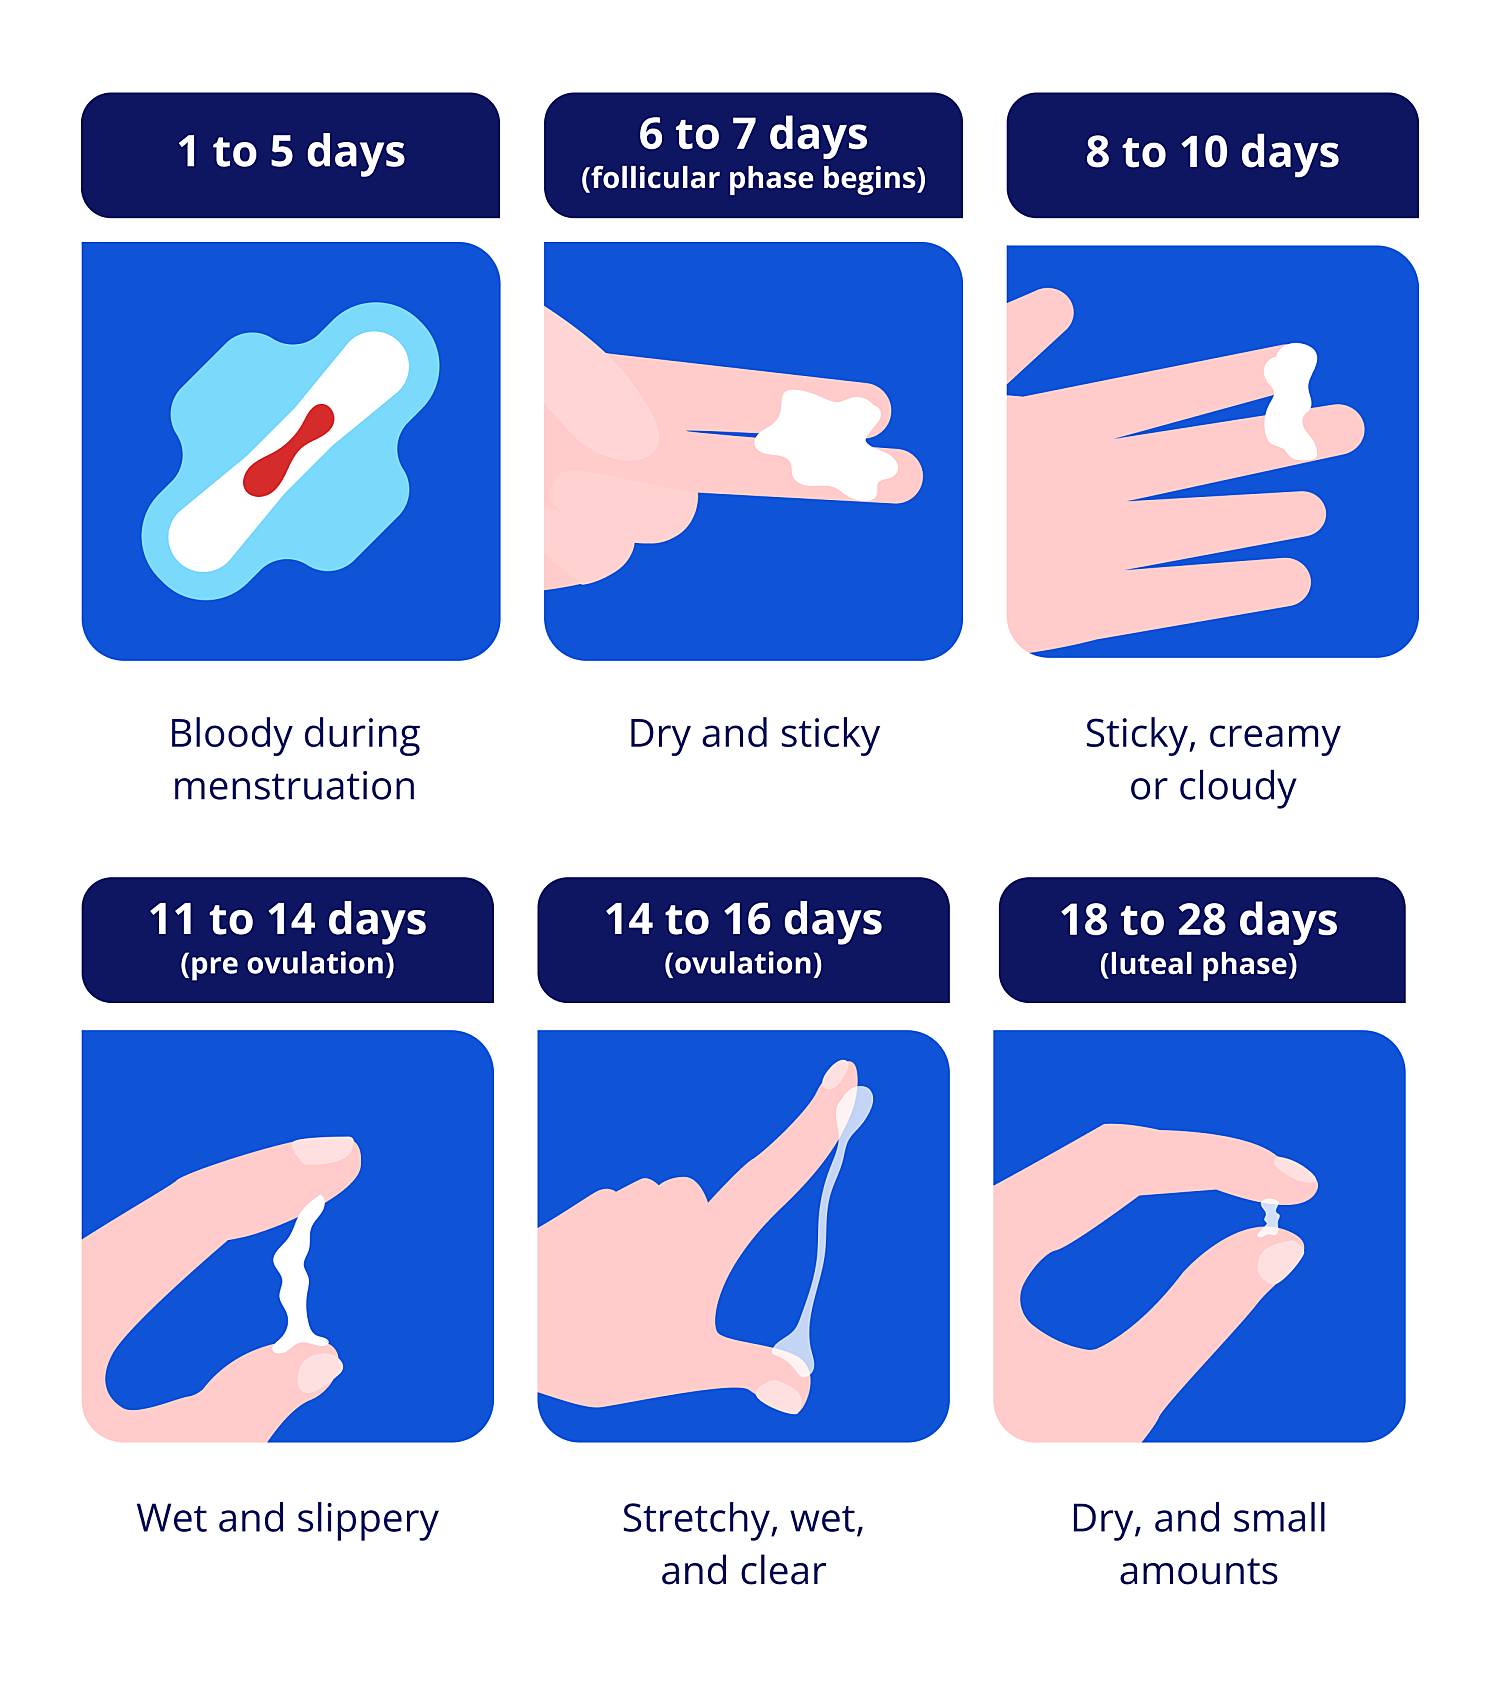
Just as a physical system requires equilibrium to function, a technological system must manage its outputs with precision. When these outputs become unregulated, they signal underlying rot, inefficiency, or compromise. To maintain a high-performance environment, one must understand the various forms of digital discharge and how to diagnose the “unhealthy” variants before they lead to systemic failure.
The Anatomy of Data Discharge: Identifying Security Leaks
In the context of digital security, “discharge” refers to the outward flow of information from a protected network. Healthy discharge includes encrypted communications, authorized API calls, and routine backups. However, unhealthy discharge—more commonly known as data exfiltration or leakage—is a silent predator that can compromise an entire organization.
Unstructured Data Seepage
Unhealthy data discharge often begins not with a massive breach, but with subtle seepage. This occurs when sensitive information moves through unauthorized channels, such as an employee using a personal cloud storage account for corporate files or developers accidentally committing API keys to public repositories.
The “look” of this discharge is often hidden in plain sight. It manifests as unusual traffic spikes during off-hours or strange destination IP addresses in firewall logs. Monitoring tools that utilize behavioral analytics can flag these discharges by identifying patterns that deviate from the established baseline. If a workstation that typically transmits 50MB of data per day suddenly discharges 5GB to an unfamiliar external server, the system is exhibiting a classic symptom of an unhealthy data leak.
API Vulnerabilities and Silent Exfiltration
Modern software relies heavily on Application Programming Interfaces (APIs). A healthy API discharge is focused, returning only the specific data requested by the authenticated user. An unhealthy discharge, however, often involves “Excessive Data Exposure,” where an API endpoint returns more information than the client needs, relying on the frontend to filter it out.
Cybercriminals exploit this by intercepting the full payload, which might contain personally identifiable information (PII) or system metadata. To diagnose this, developers must audit their JSON responses. If your API “discharges” a full user profile—including password hashes or internal IDs—when only a username was requested, you are witnessing a high-risk unhealthy discharge.
Hardware Health: Analyzing Battery and Power Discharge Patterns
In the realm of hardware and mobile technology, discharge refers to the depletion of stored energy. Every battery-operated device has a natural discharge curve, but when that curve becomes erratic or steep, it indicates a hardware or software pathology.
Background Processes and Energy Drains
One of the most common signs of unhealthy power discharge is “vampire drain.” This occurs when a device loses significant charge while in a standby or idle state. In a healthy system, low-power states (like “Deep Sleep” in Android or “Power Nap” in macOS) should minimize energy output.
Unhealthy discharge in this context often looks like a jagged line on a battery telemetry graph. Instead of a smooth, gradual decline, the graph shows sharp drops during periods of supposed inactivity. This is frequently caused by “wake locks”—software processes that prevent the CPU from entering a low-power state. Identifying these “rogue” processes is the first step in treating the hardware’s metabolic imbalance.
Thermal Throttling and Component Degradation
Energy discharge is inextricably linked to heat. When a device discharges power inefficiently, a large percentage of that energy is converted into waste heat rather than computational work. This is a primary indicator of unhealthy discharge in high-performance computing and servers.
If a processor is discharging energy at its maximum TDP (Thermal Design Power) but providing diminished clock speeds, it is likely suffering from thermal throttling. This “unhealthy” state suggests that the cooling solution has failed or that the silicon itself is degrading. Monitoring the “Performance per Watt” metric allows tech professionals to visualize this inefficiency. A healthy system maintains a stable ratio; an unhealthy one shows a discharge of heat that is disproportionate to its output.
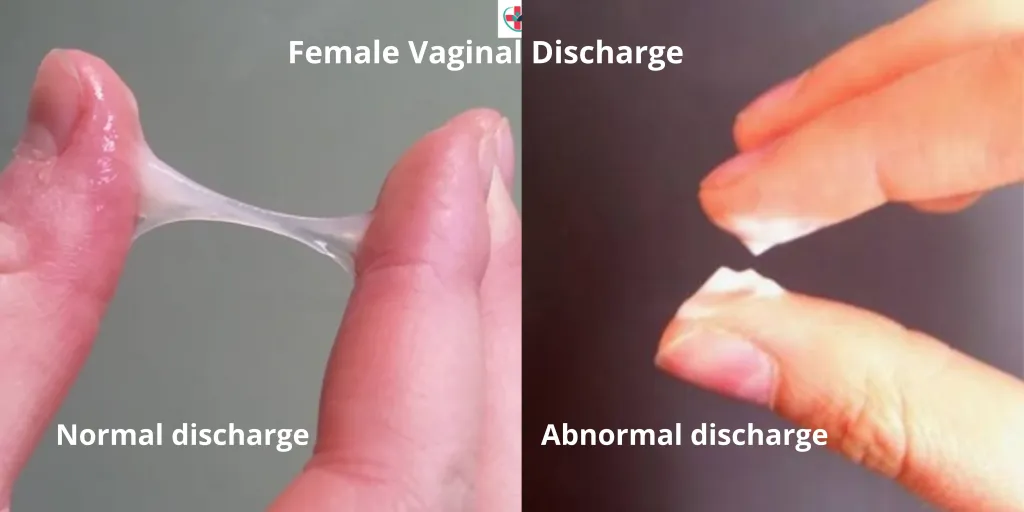
Code Rot and Resource Leaks: The Silent Performance Killers
From a software engineering perspective, discharge can be viewed as the release of system resources (RAM, CPU cycles, handles) back to the OS. When a program fails to “discharge” these resources correctly after use, the result is a “leak” that eventually suffocates the system.
Memory Leaks in Modern Software Architecture
A healthy application allocates memory for a task and discharges it (frees it) once the task is complete. Unhealthy discharge in memory management—better known as a memory leak—looks like a “staircase” pattern in a resource monitor. The RAM usage goes up as the application runs but never returns to its baseline, even when the application is idle.
In languages with Garbage Collection (GC), such as Java or C#, unhealthy discharge can be more deceptive. It may look like “GC Thrashing,” where the system is constantly trying to free up memory but failing to find objects that are safe to delete because of lingering references. This leads to high CPU spikes and “jank” in the user interface, signaling that the application is struggling to maintain a healthy resource cycle.
Redundant Requests and Server Overload
In distributed systems and web development, “unhealthy discharge” can manifest as a flood of redundant network requests. This often happens due to poorly implemented “retry” logic or a lack of caching. When a client-side app discharges hundreds of identical GET requests to a server in a few seconds, it creates a “self-inflicted DDoS” scenario.
A healthy communication flow involves “debouncing” or “throttling” these discharges. Developers should look for high “request-to-action” ratios. If one user action (like clicking a button) triggers a discharge of ten network calls, the system architecture is inefficient and prone to crashing under moderate load.
Monitoring and Mitigation Strategies for a Healthy Tech Ecosystem
Identifying what unhealthy discharge looks like is only half the battle. The final stage is implementing the tools and protocols necessary to restore health to the digital environment.
Implementing Real-Time Observability
The primary cure for unhealthy discharge is visibility. You cannot fix what you cannot see. Modern observability platforms (such as Datadog, New Relic, or Prometheus) allow teams to monitor the “telemetry” of their systems in real-time.
A healthy monitoring setup uses “threshold alerts” to notify engineers the moment a discharge becomes unhealthy. For example, if a database’s connection pool discharge rate exceeds 90% for more than three minutes, an automated alert should trigger. This proactive approach ensures that minor inefficiencies are corrected before they escalate into full-scale system outages.
Automating the Cleanup of Digital Waste
To prevent the accumulation of unhealthy discharge, automation is key. In cloud computing, this might involve “Auto-scaling” groups that discharge (terminate) unnecessary server instances to save costs and energy. In DevOps, it involves CI/CD pipelines that automatically run “static analysis” tools to find memory leaks or security vulnerabilities in the code before it is even deployed.
Furthermore, “Self-healing” architectures can detect unhealthy discharge—such as a container consuming too much memory—and automatically restart the service. By treating the tech stack as a living organism that requires constant “detoxification” from inefficient processes, organizations can ensure long-term stability and performance.
Conclusion
What does unhealthy discharge look like in the world of technology? It looks like a jagged battery graph, a staircase of rising RAM usage, a spike in unauthorized outbound data packets, and the radiating heat of a throttled processor. It is the physical and digital manifestation of waste, inefficiency, and risk.
By training ourselves to recognize these symptoms, we move from a reactive state of “fixing things when they break” to a proactive state of “optimizing for health.” Whether you are a developer writing clean code, a security analyst monitoring network traffic, or an IT manager overseeing hardware assets, your goal remains the same: to ensure that every discharge within your system is intentional, efficient, and, above all, healthy. In the fast-paced evolution of the tech landscape, the ability to diagnose and treat these digital ailments is what separates a fragile system from a resilient one.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.