
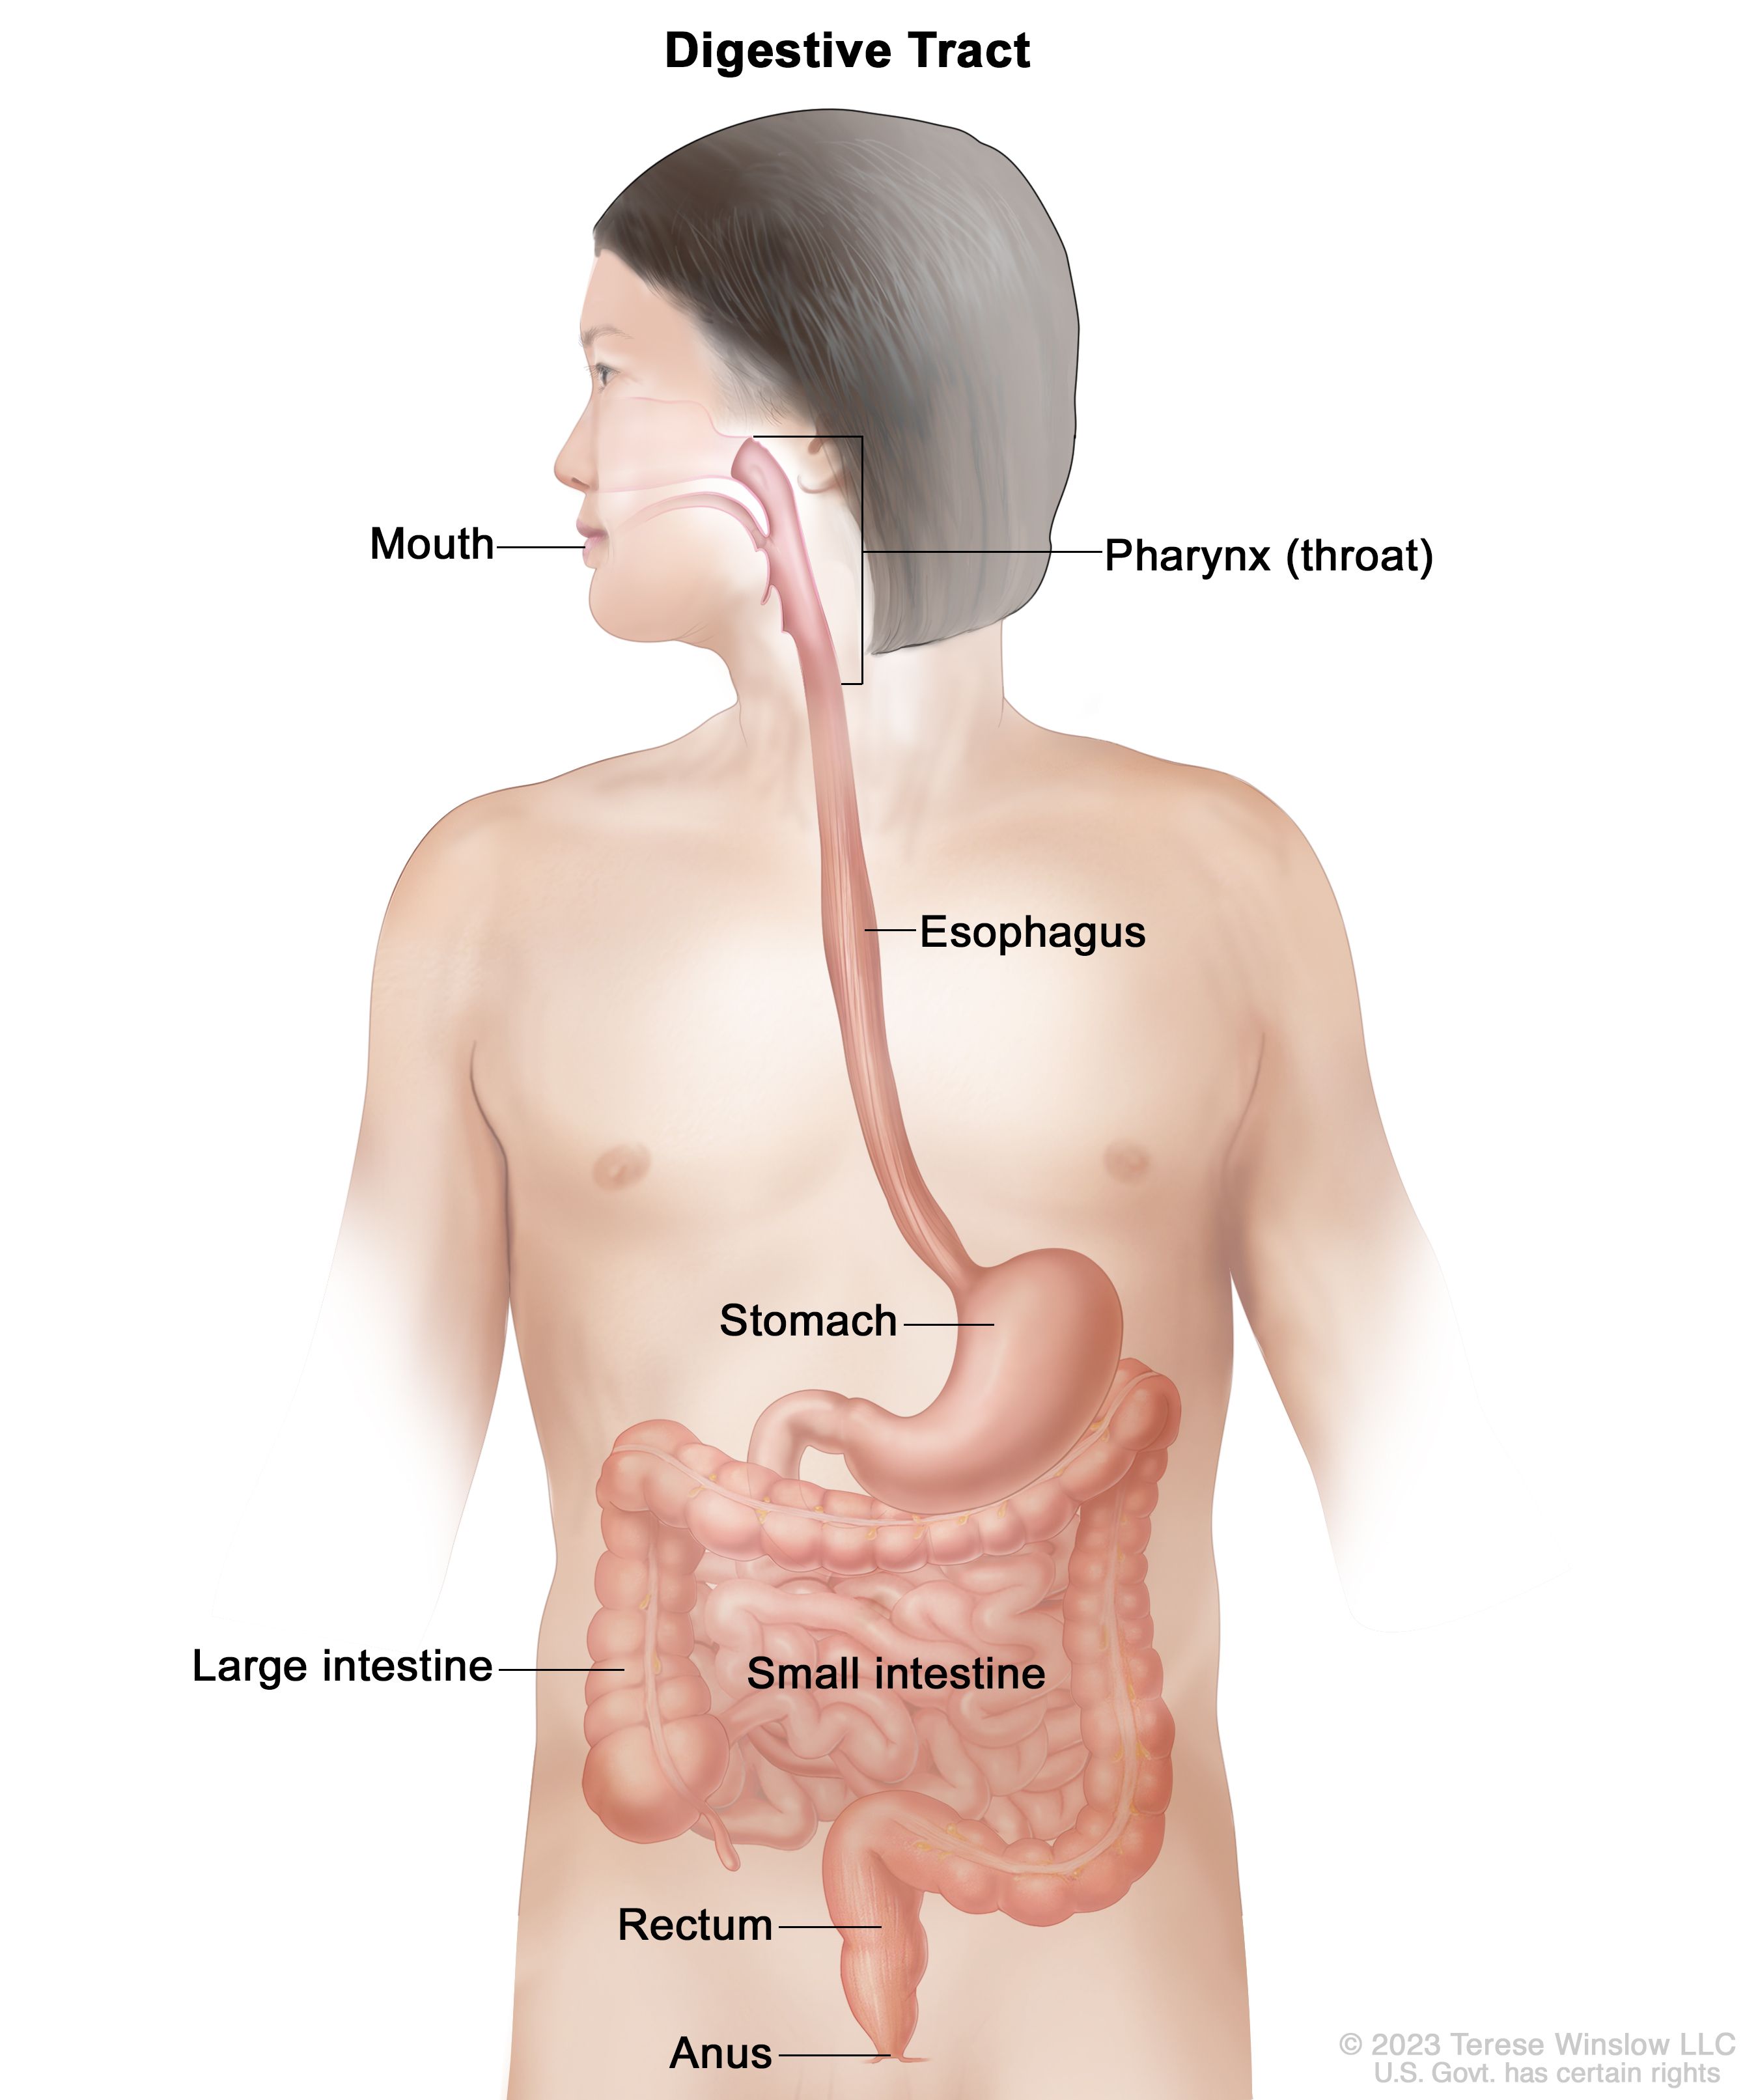
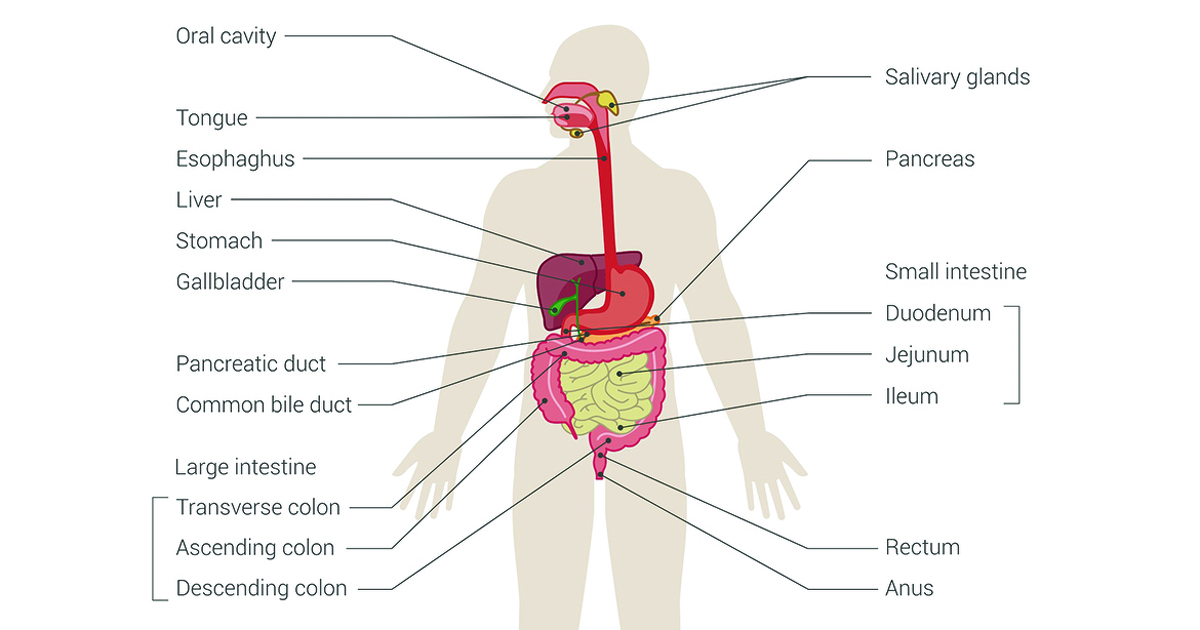
In the landscape of modern enterprise technology, the term “digestive system” has transcended its biological origins to become a powerful metaphor for how complex organizations handle information. Every software ecosystem, from a global e-commerce platform to a boutique SaaS application, possesses a functional digestive system: an intricate pipeline designed to ingest raw data, break it down into usable components, absorb its inherent value, and eliminate waste. Understanding what is inside this digital digestive system is crucial for architects, developers, and CTOs who aim to build resilient, scalable, and efficient technological infrastructures.

The digital digestive system is not a single tool but a sophisticated orchestration of layers, each performing a specific metabolic function. When we ask what is in this system, we are looking at the symbiotic relationship between ingestion engines, processing frameworks, storage matrices, and security protocols.
The Ingestion Layer: Digital Intake and the Mechanics of Raw Data Capture
The first component of any technological digestive system is the ingestion layer. Just as the biological system begins with the intake of nutrients, the technical system begins with the capture of raw data. This data arrives in various forms—unstructured, semi-structured, and structured—originating from IoT sensors, user interactions, log files, and external APIs.
Real-Time Streaming vs. Batch Processing
Within the intake stage, the system must decide how to handle the velocity of incoming “nutrients.” Modern architectures often utilize a “chewing” mechanism known as streaming. Tools like Apache Kafka or Amazon Kinesis act as the primary entry point, allowing the system to handle millions of events per second. This ensures that the organization can react to information as it happens, rather than waiting for scheduled intervals.
Conversely, batch processing represents a more traditional approach, where data is gathered over a set period and “swallowed” all at once. While slower, this method is often more efficient for deep historical analysis and heavy computational tasks. A robust digestive system utilizes a “lambda architecture,” combining both streaming and batching to ensure no data is lost and all data is prioritized based on its urgency.
The Role of Edge Computing in Data Pre-Processing
Modern tech systems have increasingly evolved to include “peripheral digestion” via edge computing. By processing data closer to the source—on mobile devices or localized gateways—the system reduces the load on its central core. This is analogous to the mechanical breakdown of food before it reaches the stomach. By filtering out noise and low-value signals at the edge, the digestive system ensures that only high-quality, actionable data reaches the cloud or the central data center, significantly reducing latency and bandwidth costs.
The Processing Core: Enzymatic Transformation and Algorithmic Enrichment
Once data has been ingested, it moves into the “stomach” of the system: the processing core. This is where the most complex transformations occur. Raw data is seldom useful in its original state; it must be cleaned, normalized, and enriched to become valuable to the business.
ETL and ELT: The Enzymatic Catalysts
In the world of data engineering, the digestive enzymes are represented by ETL (Extract, Transform, Load) or ELT (Extract, Load, Transform) processes. During transformation, the system identifies and corrects anomalies. It removes duplicate records, handles missing values, and converts data types to ensure consistency across the board.
The shift toward ELT—facilitated by powerful cloud warehouses like Snowflake and BigQuery—allows the system to “swallow” data first and “digest” it later. This provides greater flexibility, as the raw data remains available for different types of transformation as business needs evolve. In this stage, data is not just moved; it is refined into “nutrients” that the organization can actually absorb.
AI and Machine Learning as Functional Accelerants
In advanced digestive systems, artificial intelligence (AI) and machine learning (ML) models serve as specialized catalysts. These algorithms can identify patterns that are invisible to standard procedural logic. For example, a fraud detection model acts as a digestive filter, identifying “toxins” in the transaction stream and isolating them before they can affect the rest of the system.
Machine learning also enables “predictive digestion,” where the system anticipates future data loads and optimizes resource allocation in advance. By analyzing historical flow patterns, the system can scale its processing power up or down, ensuring that the “metabolic rate” of the technology matches the demands of the business environment.
The Storage Matrix: Organizing Information for Strategic Absorption
A digestive system is only as good as its ability to distribute nutrients to where they are needed most. In technology, this is handled by the storage matrix—a tiered architecture of databases, data lakes, and warehouses that store information based on its accessibility requirements and value.
Data Lakes vs. Data Warehouses
The “small intestine” of the digital digestive system can be split into two primary structures: the data lake and the data warehouse. A data lake (such as Amazon S3 or Azure Data Lake Storage) acts as a vast reservoir for raw, unprocessed data. It is highly scalable and cost-effective, allowing the system to keep information that might not have an immediate use but could be valuable for future analysis.
The data warehouse, on the other hand, is a highly structured environment where “digested” data is stored for rapid retrieval. This is where the organization’s “vital nutrients” reside—clean, verified data that feeds Business Intelligence (BI) tools and executive dashboards. The interplay between these two storage types ensures that the system is both flexible enough to store everything and organized enough to find anything.
Indexing and Query Optimization
Absorption requires efficiency. If the system cannot retrieve data quickly, the “nutrients” go to waste. This is where indexing and query optimization come into play. Modern query engines like Presto or Trino allow developers to scan petabytes of data in seconds. By creating sophisticated maps of where data lives, the system ensures that when an application or a user requests information, it can be delivered with minimal latency. This “absorptive efficiency” is what separates high-performance tech stacks from those that struggle with technical debt and sluggish performance.
Security and Governance: The Immune System Within the Infrastructure
No digestive system can survive without an immune system to protect it from external threats and internal malfunctions. In the context of technology, this involves security protocols, encryption, and data governance frameworks.
Zero-Trust Architecture and Encryption
Security is not an afterthought; it is integrated into every “organ” of the digestive system. From the moment data enters the ingestion layer, it must be protected. Encryption at rest and encryption in transit serve as the primary barriers against data breaches. Furthermore, the adoption of “Zero-Trust” architectures ensures that no part of the system is inherently trusted. Every data packet must be verified, and every user must be authenticated before they can access the “nutrients” within the storage matrix.
Governance, Compliance, and Ethical Oversight
What is in the digestive system must also be legal and ethical. Data governance frameworks act as the system’s regulatory body, ensuring compliance with global standards such as GDPR, CCPA, and SOC2. This involves maintaining a clear “lineage” of data—knowing where it came from, how it was transformed, and who has access to it.
Effective governance prevents the system from “digesting” sensitive information in a way that violates privacy. It ensures that data is used responsibly and that the organization remains healthy and compliant in an increasingly regulated digital world. This level of oversight is essential for maintaining the “health” of the brand and the trust of the end-user.
Optimization and Feedback Loops: The Nervous System of Data Digestion
The final component of the digital digestive system is the feedback loop. Just as the biological nervous system monitors the digestive process and sends signals to adjust acidity or speed, modern tech stacks use observability and monitoring tools to maintain equilibrium.
Observability and Telemetry
Tools like Datadog, New Relic, and Prometheus provide the “nervous system” for the tech stack. They collect telemetry data—metrics, logs, and traces—that allow engineers to monitor the health of the digestive process in real-time. If a specific “organ” (such as a microservice or a database) is struggling under a high load, the system can trigger automated alerts or auto-scaling events to alleviate the pressure.
Continuous Integration and Continuous Deployment (CI/CD)
The digestive system must also evolve. CI/CD pipelines represent the evolutionary mechanism of the technology stack. They allow developers to introduce new “enzymes” (features or optimizations) into the system without disrupting the ongoing digestive process. By automating the testing and deployment of code, the organization ensures that its digestive system remains modern, efficient, and capable of handling new types of data “nutrients” as they emerge in the marketplace.
The question of “what is in the digestive system” reveals a complex, multi-layered architecture that is fundamental to the survival of any tech-driven enterprise. By viewing data through the lens of ingestion, transformation, storage, and protection, organizations can build systems that do more than just store information—they create value, drive innovation, and ensure long-term operational health.
aViewFromTheCave is a participant in the Amazon Services LLC Associates Program, an affiliate advertising program designed to provide a means for sites to earn advertising fees by advertising and linking to Amazon.com. Amazon, the Amazon logo, AmazonSupply, and the AmazonSupply logo are trademarks of Amazon.com, Inc. or its affiliates. As an Amazon Associate we earn affiliate commissions from qualifying purchases.